Best AI · Customer support
The best AI for customer support
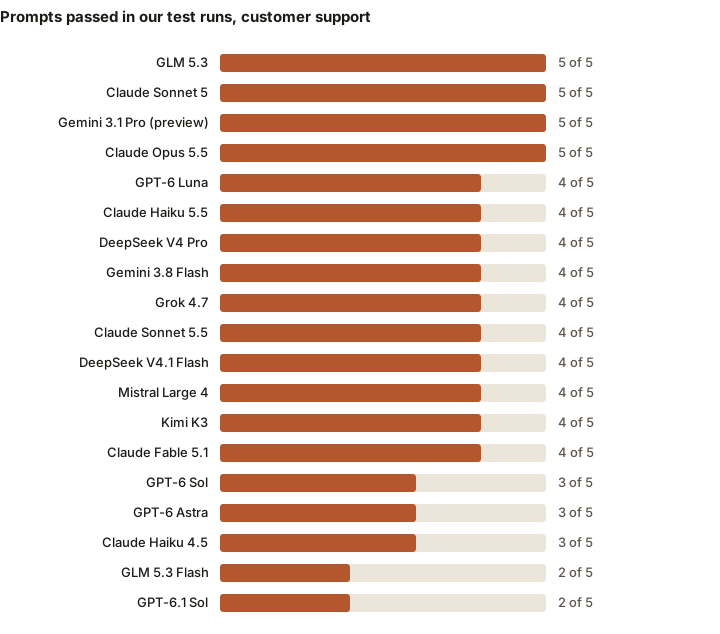
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026, 4 of the 19 models passed 5 of 5 customer support prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 95 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 9, 2026, 4 models passed 5 of 5 customer support prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday customer support, GPT-6 Luna (4 of 5), from the daily count.
Our picks for customer support
Hard problems
Shared by 4 models
4 models passed 5 of 5, both hard ones: Claude Opus 5.5, Claude Sonnet 5, Gemini 3.1 Pro and GLM 5.3. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 customer support prompts, with 250 a month on Pro.
Everyday
Passed 4 of 5 customer support prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 19 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our customer support test runs, model by model
How each model did on our 5 customer support prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 4 of 5 | 1 of 2 | 1 each, of 31 a month on Pro | $0.0221 | 5.9 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0108 | 6.5 s |
| Claude Sonnet 5.5Anthropic | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0046 | 3.1 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0036 | 3.7 s |
| Claude Haiku 5.5Anthropic | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 2.4 s |
| Claude Haiku 4.5Anthropic | 3 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0015 | 2.6 s |
| GPT-6 AstraOpenAI | 3 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0116 | 3.6 s |
| GPT-6.1 SolOpenAI | 2 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0012 | 3.0 s |
| GPT-6 SolOpenAI | 3 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0029 | 3.6 s |
| GPT-6 LunaOpenAI | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.4 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0106 | 8.7 s |
| Gemini 3.8 FlashGoogle | 4 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0016 | 4.6 s |
| DeepSeek V4.1 FlashDeepSeek | 4 of 5 | 1 of 2 | 1 each, of 60 a day on Pro | $0.0005 | 1.4 s |
| DeepSeek V4 ProDeepSeek | 4 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0015 | 4.8 s |
| Grok 4.7xAI | 4 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0061 | 9.8 s |
| Kimi K3Moonshot | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0046 | 5.3 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0005 | 2.6 s |
| GLM 5.3 FlashZ.ai | 2 of 5 | 1 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 5.4 s |
| Mistral Large 4Mistral | 4 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0015 | 7.2 s |
One prompt, side by side
Each model's reply to “A refund request outside the window”, as it came, with whether it passed and what it cost.
The prompt: A refund request outside the window (hard)
Northwind Outfitters support policy
- Returns: within 30 days of delivery, unworn items with tags get a full refund to the original payment method.
- After 30 days and up to 60 days: exchange or a store gift card only, no refund.
- Refunds are paid within 5 business days of the return reaching our warehouse.
- Standard delivery takes 3 to 5 business days. If an order is more than 7 business days late, the customer gets free express shipping on their next order.
- Staff can't give discount codes worth more than 15%.

Customer message: "I bought a coat 45 days ago and never wore it. I'd like a refund to my card, please."

Write the reply to the customer, following the policy. At most 150 words, signed "Sam, Northwind support".
Claude Opus 5.5
Passed: Graded 5.0 of 5 on average (lowest 5).
Hi there,

Thank you for reaching out about your coat.

Our policy offers full refunds to the original payment method for unworn items with tags returned within 30 days of delivery. Since your purchase was about 45 days ago, it's outside the refund window, so unfortunately I can't refund it to your card.

Because it's still within 60 days, you can choose either:
- **An exchange** for a different size, colour, or item, or
- **A store gift card** for the full value.

Please make sure the coat is unworn with its tags still attached. Just let me know which option you'd prefer, and I'll send you the return instructions.

Sorry I can't offer a card refund this time, and thanks for your understanding.

Best regards,
Sam, Northwind support
706 tokens in, 355 out (114 of them reasoning) · 6.1 s · $0.0106 · 1 message on Pro · answered by anthropic/claude-opus-5.5 via Claude Platform on AWS ·
GLM 5.3
Passed: Graded 4.7 of 5 on average (lowest 4).
Hi,

Thanks for reaching out! Since your coat was delivered 45 days ago, it falls outside our 30-day refund window, so I'm unable to refund your card. However, because it's within 60 days and unworn with tags, you're eligible for either an exchange or a store gift card for the item's value.

Just reply with which option you'd prefer and we'll get it sorted right away.

Sorry for the inconvenience, and thanks for understanding!

Sam, Northwind support
553 tokens in, 115 out (13 of them reasoning) · 1.1 s · $0.0009 · 1 message on Pro · answered by z-ai/glm-5.3 via Wafer ·
GPT-6 Luna
Passed: Graded 4.7 of 5 on average (lowest 4).
Hi,

Since your coat was purchased 45 days ago, it’s outside our 30-day refund window. However, within 60 days, unworn items are eligible for an exchange or a store gift card. We’re sorry we can’t refund it to your card.

Sam, Northwind support
511 tokens in, 64 out · 1.3 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The customer support prompts, and how they're scored
Rubric (graded). The grader model scores the reply from 1 to 5 on each published criterion. It passes with an average of 4 or more and no criterion under 3, and only if it also meets the prompt's automatic rules (length, words it must or mustn't use).
The grader is Claude Opus 5.5 at low reasoning effort; its own replies are graded by GPT-6 Astra, so no model grades itself. Its prompt and every rubric are on the methods page.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five customer support prompts and how every reply was scored.
Prompts like these to try yourself
What matters for customer support
Tone
Support replies need to sound calm and human, and match your brand. Give the model examples of replies you like.
Accuracy about your product
A model only knows your product if you tell it. Paste the policy or attach the help article, and ask it to stick to them.
Cost at volume
Support is high volume. A fast, low-cost model handles most drafts; a stronger one is worth it for the tricky few.
Languages
Customers write in many languages. Most models can draft replies in the customer's language; check anything important with a native speaker.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | 1 message | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | Yes | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | Yes | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Customer support in llmwise
A persona for your team's voice
Create a persona with your tone, policies and sign-off, and a default model. Every chat started with it follows the same instructions.
Answers from your own docs
Attach your help-center pages or policy PDFs (up to 100 pages each) so replies follow what your product actually does.
Everyday models for volume
Everyday models don't touch the monthly allowance: a paid plan has 60 to 200 a day. Save the bigger models for the hard replies.
Switch models mid-chat
Start on a cheaper model; if the answer isn't good enough, switch models in the same chat. The next model sees the whole conversation, so you don't paste anything twice.
Tips
Paste the customer's message and the relevant policy together.
Ask for a draft and a shorter version, then pick.
Ask the model to flag anything it isn't sure is true about your product.
Summarize a long thread before replying, so nothing gets missed.
Questions
What is the best AI for customer support?
In our test runs on October 9, 2026, 4 of the 19 models passed 5 of 5 customer support prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, GPT-6 Luna (4 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for customer support?
We sent the same customer support prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for customer support for free?
Yes, to try: Free is a one-time trial of 5 messages on every model but Claude Fable 5.1 and GPT-6 Astra (one of them can be on Claude Opus 5.5).
Can llmwise answer my customers automatically?
No. llmwise is a chat app for people. It helps an agent draft, summarize and translate replies, but it doesn't connect to a help desk or answer customers on its own.
Where do the customer messages I paste go?
A message goes to the company whose model answers it, or through OpenRouter when a request is routed through it. DeepSeek, Mistral, Kimi, Grok, and GLM are served only by endpoints that don't store or train on prompts. Leave out anything you wouldn't send to that provider.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.