Blog · September 24, 2026
Updated · By llmwise, AI-assisted.
LLM routing, explained
LLM routing sends each request to a model picked for it, instead of one model for everything. Routers pick by fixed rules, by a small classifier's guess, or by trying a cheap model first, and they fall back when a provider fails. llmwise doesn't route for you: you pick each model, and see its count first.
Four ways routers decide
Rules
Fixed rules send each kind of request to a set model: summaries here, code there. Predictable, and blind to how hard a particular request is.
Classifiers
A small model reads each request and guesses how hard it is, then picks a model to match. Cheaper on average, but you don't see why a model was picked. Microsoft's model router and Amazon's Bedrock prompt routing both work this way.
Cascades
Try a cheap model first and escalate to a stronger one when the answer looks weak. Good value when most requests are easy.
Fallback
When a provider fails or is slow, send the request to another route. OpenRouter's provider docs describe it: skip hosts with a recent outage, and keep the rest as fallbacks. About staying up, not about quality.
Does a cascade pay off? Our test prompts, worked through
We sent 50 prompts to GPT-6 Luna, an everyday model, and to Claude Opus 5.5, a flagship, in our test runs of September 27, 2026. GPT-6 Luna passed 47. Sending only its 3 misses on to Claude Opus 5.5 brings the total to 50, for 8% of what Claude Opus 5.5 cost on every prompt.
| How the prompts were answered | Passed | What OpenRouter charged |
|---|---|---|
| GPT-6 Luna alone | 47 of 50 | $0.0059 |
| Claude Opus 5.5 alone | 49 of 50 | $0.5360 |
| GPT-6 Luna, then Claude Opus 5.5 on its 3 misses | 50 of 50 | $0.0424 |
The catch is the step a table hides. Our grader knew which replies failed; a live router has to guess, and every guess it gets wrong either wastes a flagship call or lets a weak answer through. That guess is the hard part of routing. Every prompt and reply is on our test runs page.
Where automatic routing falls short
It guesses. A request that looks easy can be hard, and the router only finds out after a weak answer.
It's opaque. You rarely see which model answered or why, so you can't tell a bad model from a bad pick.
It makes cost hard to predict: the same question can cost different amounts on different days.
For an app answering thousands of requests, those trade-offs can be worth it. For a person asking a question, you usually know better than a router how much the answer matters.
Why llmwise lets you pick
In llmwise the router is you, with the information a router would use. The picker shows how many messages you have left on each model before you send, and switching mid-chat keeps the whole conversation. A manual cascade looks like this:
Everyday models: quick questions, rewrites, lookups and anything you ask often.
Models with 125 to 250 messages a month on Pro: most real work: writing, explaining, analysis and code, where a better answer is worth one of your monthly messages.
Models with 31 to 62 messages a month on Pro: the hardest problems, where getting it right matters more than the price.
Start with the first and move to the next only when an answer isn't good enough. See which model to use when.
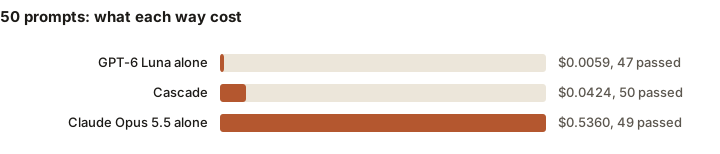
LLM routing: questions
Does llmwise route my messages automatically?
No. You pick the model for each message, and the picker shows how many messages you have left on it before you send. The one kind of routing llmwise does is fallback: when it can't reach a model's maker directly, it reaches the model through OpenRouter.
Route by hand, with the price in view
llmwise doesn't pick a model for you: you choose one for each message and see what it costs before you send.