Best AI · RAG and answering from documents
The best AI for RAG and answering from documents
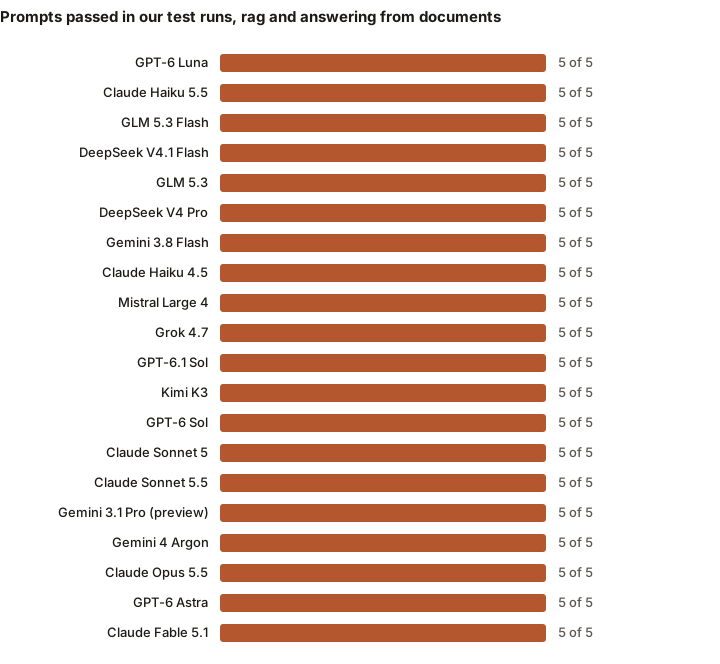
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 15, 2026, 20 of the 20 models passed 5 of 5 RAG and answering from documents prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 100 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 15, 2026, all 20 models passed 5 of 5 RAG and answering from documents prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday RAG and answering from documents, GPT-6 Luna (5 of 5), from the daily count.
Our picks for RAG and answering from documents
Hard problems
Shared by 20 models
All 20 models passed 5 of 5, both hard ones: Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5 and 17 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 RAG and answering from documents prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 RAG and answering from documents prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 20 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our RAG and answering from documents test runs, model by model
How each model did on our 5 RAG and answering from documents prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0145 | 4.9 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0073 | 3.8 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0028 | 1.3 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0022 | 1.9 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.2 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0010 | 1.3 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0079 | 1.8 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0008 | 1.5 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0016 | 1.3 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.3 s |
| Gemini 4 ArgonGoogle | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0012 | 3.6 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0058 | 6.2 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0007 | 3.2 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 0.5 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0006 | 3.1 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0029 | 2.4 s |
| Kimi K3Moonshot | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0015 | 3.2 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0005 | 0.8 s |
| GLM 5.3 FlashZ.ai | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 2.3 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0014 | 11.1 s |
One prompt, side by side
Each model's reply to “A later amendment changes the answer”, as it came, with whether it passed and what it cost.
The prompt: A later amendment changes the answer (hard)
Answer only from the handbook below, and cite the section you used, like (§3). If the handbook doesn't say, reply that it isn't in the handbook.

Harbor & Pine employee handbook (excerpt)

§1 Working hours. Core hours are 10:00 to 16:00. You can start any time between 07:30 and 10:00.
§2 Remote work. Staff can work remotely up to 3 days a week; interns 1 day a week. Requests to work fully remote go to the People team.
§3 Equipment. Laptops are replaced every 4 years. Monitors are available on request. New staff get a one-time home office stipend of €600 when they start.
§4 Parental leave. Every parent gets 16 weeks of leave at full pay. It can be split into two blocks, both taken within the child's first year.
§5 Holidays. Staff get 27 days a year plus public holidays. Up to 5 unused days carry over to the next year.
§6 Learning. Each person has €1,200 a year for courses and books. Unused learning budget doesn't carry over.
§7 Amendments (1 September 2026). For everyone who joins on or after 1 September 2026, the home office stipend in §3 is €900. Remote work for interns in §2 rises to 2 days a week.

Question: I'm an intern who started on 15 September 2026. How many days a week can I work remotely, and how big is my home office stipend?
Claude Fable 5.1
Passed: Stated all 3 facts with the section.
As an intern who joined on 15 September 2026 (on or after 1 September 2026), the amendments apply to you:

- **Remote work:** 2 days a week (§7, amending §2).
- **Home office stipend:** €900 one-time, since you're new staff starting after the amendment date (§7, amending §3).
919 tokens in, 104 out · 7.1 s · $0.0165 · 1 message on Pro · answered by anthropic/claude-fable-5.1 via Anthropic ·
GLM 5.3
Passed: Stated all 3 facts with the section.
You can work remotely 2 days a week (§7), and your home office stipend is €900 (§7).
704 tokens in, 60 out (33 of them reasoning) · 1.3 s · $0.0006 · 1 message on Pro · answered by z-ai/glm-5.3 via Wafer ·
GPT-6 Luna
Passed: Stated all 3 facts with the section.
You can work remotely up to 2 days a week, and your home office stipend is €900 (§2, §3, §7).
659 tokens in, 33 out · 1.0 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The RAG and answering from documents prompts, and how they're scored
Key facts. Automatic. The answer must state each fact the handbook gives and cite its section, or say plainly that the handbook doesn't answer the question.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five RAG and answering from documents prompts and how every reply was scored.
Prompts like these to try yourself
What matters for RAG and answering from documents
Room for the documents
The whole point is answering from your material, so the model must fit it: context windows are listed below.
Sticking to the sources
A good model answers from the text you gave it, says when the answer isn't there, and doesn't fill gaps from memory.
Citations
Quotes and page references let you check an answer in seconds.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | No | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 4 ArgonGoogle | 62/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | No | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
RAG and answering from documents in llmwise
Attach your documents
Attach PDFs (up to 100 pages), images, Word, Excel, and PowerPoint files, and text or code files (plain text, Markdown, and CSV, JSON and more), up to 10 files a message.
Web search with sources
The model can search the web and cite what it found as source cards, or read a link you paste. On Free, web search works inside your 5 trial messages; on a paid plan a search counts as one more message of the model in use.
Skills with reference files
Put reference documents in a skill; the model reads the files it needs when a question calls for them.
Long chats, stated up front
Past 64k tokens each reply counts as 2, past 128k as 4, and a chat stops at 200k; the composer says so before you send. One document set per chat keeps it short.
Tips
Ask the model to quote the passage each answer comes from.
Tell it to say so when the documents don't contain the answer.
Keep one set of documents per chat.
For a scanned PDF, use a model that takes the whole file: others only get the PDF's text.
Questions
What is the best AI for RAG and answering from documents?
In our test runs on October 15, 2026, 20 of the 20 models passed 5 of 5 RAG and answering from documents prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, GPT-6 Luna (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for RAG and answering from documents?
We sent the same RAG and answering from documents prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for RAG and answering from documents for free?
Yes, to try: Free is a one-time trial of 5 messages on Claude Haiku 5.5.
Is attaching files the same as RAG?
Close to it. Retrieval-augmented generation means giving a model the relevant material at question time, so it answers from that rather than from memory. In llmwise you do that by attaching files, pasting links or letting the model search the web.
Can I build a RAG app on llmwise?
No. llmwise is a chat app with no API; building a RAG pipeline into your own product means calling a model provider's API from your code.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.