Best AI · SQL
The best AI for SQL
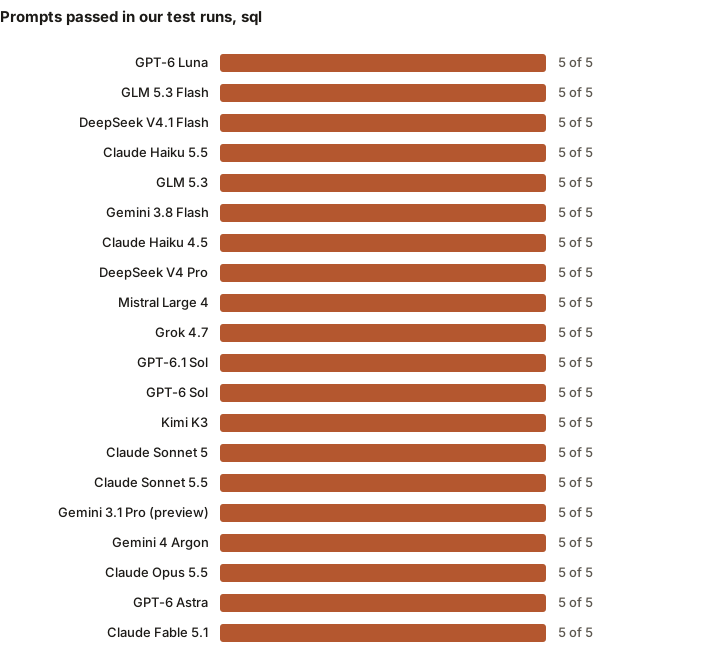
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 15, 2026, 20 of the 20 models passed 5 of 5 SQL prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 100 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 15, 2026, all 20 models passed 5 of 5 SQL prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday SQL, GPT-6 Luna (5 of 5), from the daily count.
Our picks for SQL
Hard problems
Shared by 20 models
All 20 models passed 5 of 5, both hard ones: Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5 and 17 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 SQL prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 SQL prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 20 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our SQL test runs, model by model
How each model did on our 5 SQL prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0185 | 4.5 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0092 | 4.4 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0038 | 1.9 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0028 | 2.5 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 1.6 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0010 | 1.4 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0098 | 2.8 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0010 | 2.0 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0021 | 1.9 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.5 s |
| Gemini 4 ArgonGoogle | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0012 | 3.1 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0077 | 7.3 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0007 | 3.6 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 0.7 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0020 | 7.4 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0048 | 6.1 s |
| Kimi K3Moonshot | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0024 | 1.9 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0003 | 1.5 s |
| GLM 5.3 FlashZ.ai | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.7 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0022 | 9.3 s |
One prompt, side by side
Each model's reply to “Every customer, even those without orders”, as it came, with whether it passed and what it cost.
The prompt: Every customer, even those without orders (hard)
An online shop's SQLite database:
CREATE TABLE customers (id INTEGER PRIMARY KEY, name TEXT NOT NULL, country TEXT NOT NULL, signed_up TEXT NOT NULL);
CREATE TABLE products (id INTEGER PRIMARY KEY, name TEXT NOT NULL, category TEXT NOT NULL, price_cents INTEGER NOT NULL);
CREATE TABLE orders (id INTEGER PRIMARY KEY, customer_id INTEGER NOT NULL REFERENCES customers(id), ordered_on TEXT NOT NULL, status TEXT NOT NULL);
CREATE TABLE order_items (order_id INTEGER NOT NULL REFERENCES orders(id), product_id INTEGER NOT NULL REFERENCES products(id), quantity INTEGER NOT NULL);

For every customer, show their name, the date of their first order that wasn't cancelled, and how many orders that weren't cancelled they have. Include customers who have no such orders, with NULL for the date and 0 for the count. Sort by name.
Write one SQLite query and reply with it in a ```sql code block.
Claude Fable 5.1
Passed: Returned the right 8 rows.
```sql
SELECT c.name,
       MIN(o.ordered_on) AS first_order_date,
       COUNT(o.id)       AS order_count
FROM customers c
LEFT JOIN orders o
       ON o.customer_id = c.id
      AND o.status <> 'cancelled'
GROUP BY c.id, c.name
ORDER BY c.name;
```

The status filter is in the `ON` clause (not `WHERE`) so customers with only cancelled orders or no orders are still kept, yielding `NULL` and `0`.
861 tokens in, 185 out · 5.2 s · $0.0199 · 1 message on Pro · answered by anthropic/claude-fable-5.1 via Anthropic ·
GLM 5.3
Passed: Returned the right 8 rows.
```sql
SELECT c.name,
       MIN(o.ordered_on) AS first_order_date,
       COUNT(o.id) AS order_count
FROM customers c
LEFT JOIN orders o
  ON o.customer_id = c.id AND o.status != 'cancelled'
GROUP BY c.id, c.name
ORDER BY c.name;
```
562 tokens in, 68 out (1 of them reasoning) · 1.0 s · $0.0007 · 1 message on Pro · answered by z-ai/glm-5.3 via Wafer ·
GPT-6 Luna
Passed: Returned the right 8 rows.
```sql
SELECT
  c.name,
  MIN(CASE WHEN o.status <> 'cancelled' THEN o.ordered_on END) AS first_order_date,
  COUNT(CASE WHEN o.status <> 'cancelled' THEN o.id END) AS order_count
FROM customers AS c
LEFT JOIN orders AS o
  ON o.customer_id = c.id
GROUP BY c.id, c.name
ORDER BY c.name;
```
522 tokens in, 92 out · 2.4 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The SQL prompts, and how they're scored
Query result. Automatic. The query runs against a small SQLite database and must return the same rows as our reference query (column names and order don't matter; row order does when the prompt asks for it).
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five SQL prompts and how every reply was scored.
Prompts like these to try yourself
What matters for SQL
Knowing your schema
Without your schema a model guesses table and column names. With it, most queries come out right first time.
The right dialect
Date functions, string handling and upserts differ between databases. Say which one you use.
Correctness
A query that runs isn't always a query that's right. Test it on sample data before running it on production.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | No | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 4 ArgonGoogle | 62/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | No | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
SQL in llmwise
Your schema in the chat
Paste your CREATE TABLE statements or attach them as a text file, so queries use your real table and column names.
Test queries (Pro and higher plans)
On Pro and higher plans the model can test a query: for example, load a CSV you attach into SQLite with Python and run it. A run counts as 1 Claude Haiku 4.5 message.
Queries as documents
Ask for a query and it opens as a code document that keeps every version.
Switch models mid-chat
Start on a cheaper model; if the answer isn't good enough, switch models in the same chat. The next model sees the whole conversation, so you don't paste anything twice.
Tips
Give the CREATE TABLE statements and a few sample rows.
Name the database and version.
Ask it to explain the query line by line before you run it.
For slow queries, share the query plan and ask about indexes.
Questions
What is the best AI for SQL?
In our test runs on October 15, 2026, 20 of the 20 models passed 5 of 5 SQL prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, GPT-6 Luna (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for SQL?
We sent the same SQL prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for SQL for free?
Yes, to try: Free is a one-time trial of 5 messages on Claude Haiku 5.5.
Can it connect to my database?
Not by itself. llmwise doesn't connect to your database. Paste the schema instead; on Pro and higher plans you can connect an MCP server that gives the model database tools, if you run one.
Which SQL dialects does it write?
Any the model knows well: PostgreSQL, MySQL, SQLite, SQL Server, BigQuery and so on. Name yours and its version in the first message.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.