Best AI · Summarization
The best AI for summarization
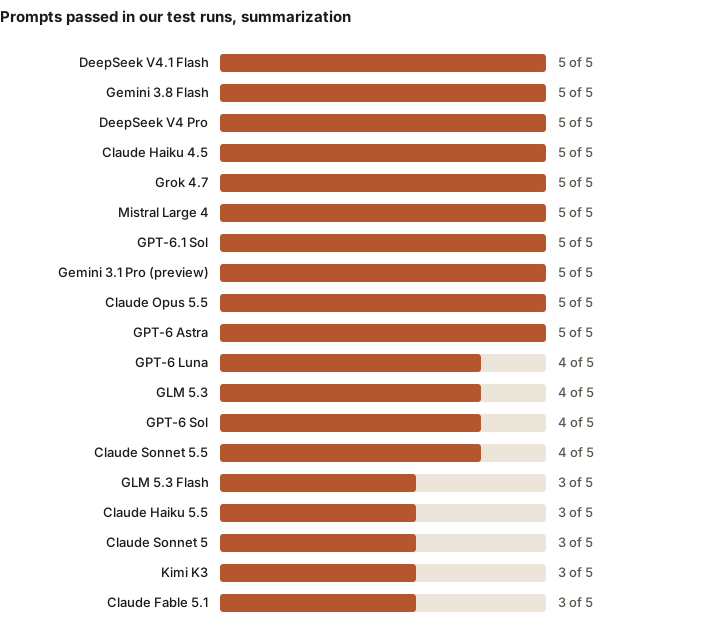
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026, 10 of the 19 models passed 5 of 5 summarization prompts, so these prompts don't name one best model. For best value, Gemini 3.8 Flash (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 95 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 9, 2026, 10 models passed 5 of 5 summarization prompts, so these prompts don't pick one for hard problems. For value, Gemini 3.8 Flash (5 of 5), 250 a month on Pro; for everyday summarization, DeepSeek V4.1 Flash (5 of 5), from the daily count.
Our picks for summarization
Hard problems
Shared by 10 models
10 models passed 5 of 5, both hard ones: Claude Opus 5.5, Claude Haiku 4.5, GPT-6 Astra and 7 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 summarization prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 summarization prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 19 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our summarization test runs, model by model
How each model did on our 5 summarization prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 3 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0161 | 4.6 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0095 | 4.7 s |
| Claude Sonnet 5.5Anthropic | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0034 | 2.0 s |
| Claude Sonnet 5Anthropic | 3 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0028 | 2.7 s |
| Claude Haiku 5.5Anthropic | 3 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0003 | 3.0 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0010 | 1.9 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0109 | 3.0 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0010 | 2.0 s |
| GPT-6 SolOpenAI | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0022 | 2.4 s |
| GPT-6 LunaOpenAI | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.4 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0088 | 8.3 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0008 | 3.7 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 0.9 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0009 | 2.6 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0028 | 3.5 s |
| Kimi K3Moonshot | 3 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0034 | 6.3 s |
| GLM 5.3Z.ai | 4 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0005 | 1.4 s |
| GLM 5.3 FlashZ.ai | 3 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 4.4 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0043 | 27.3 s |
One prompt, side by side
Each model's reply to “A quarterly memo for the CEO”, as it came, with whether it passed and what it cost.
The prompt: A quarterly memo for the CEO (hard)
Summarize this memo for the CEO in at most 4 sentences, keeping every number exact.

Q3 at Fernway: revenue was $2.4M, up 18% on Q2, driven by the new team plan, which now makes up 41% of new sign-ups. Churn fell from 3.1% to 2.6% a month. Gross margin slipped from 71% to 68% because of higher hosting costs, which the platform team expects to bring back down by the end of Q4 after moving storage providers. We ended the quarter with 14 months of runway. Hiring is frozen until Q2 next year, except for two support roles already approved. The biggest risk is our largest customer, 9% of revenue, whose contract is up for renewal in November.
Claude Opus 5.5
Passed: Graded 5.0 of 5 on average (lowest 5).
Fernway's Q3 revenue was $2.4M, up 18% on Q2, driven by the new team plan, which now accounts for 41% of new sign-ups, while monthly churn fell from 3.1% to 2.6%. Gross margin slipped from 71% to 68% due to higher hosting costs, which the platform team expects to bring down by the end of Q4 after switching storage providers. We ended the quarter with 14 months of runway, and hiring is frozen until Q2 next year except for two already-approved support roles. The biggest risk is our largest customer, 9% of revenue, whose contract is up for renewal in November.
695 tokens in, 206 out · 3.5 s · $0.0075 · 1 message on Pro · answered by anthropic/claude-opus-5.5 via Claude Platform on AWS ·
Gemini 3.8 Flash
Passed: Graded 4.7 of 5 on average (lowest 4).
Q3 revenue reached $2.4M (up 18% on Q2), propelled by the new team plan accounting for 41% of new sign-ups, while monthly churn dropped from 3.1% to 2.6%. Gross margin declined from 71% to 68% due to hosting costs, though a storage migration is expected to resolve this by the end of Q4. The company holds 14 months of runway, with hiring frozen until Q2 next year aside from two approved support roles. The primary risk is the upcoming November renewal for Fernway's largest customer, which represents 9% of revenue.
537 tokens in, 136 out · 4.0 s · $0.0009 · 1 message on Pro · answered by google/gemini-3.8-flash via Google ·
DeepSeek V4.1 Flash
Passed: Graded 4.7 of 5 on average (lowest 4).
Q3 revenue reached $2.4M, up 18% on Q2, driven by the new team plan, now 41% of new sign-ups. Monthly churn fell from 3.1% to 2.6%, but gross margin slipped from 71% to 68% on higher hosting costs, which the platform team expects to restore by the end of Q4 after switching storage providers. We ended the quarter with 14 months of runway, hiring is frozen until Q2 next year except for two already-approved support roles. The biggest risk is our largest customer, 9% of revenue, whose contract renews in November.
545 tokens in, 145 out (10 of them reasoning) · 0.4 s · $0.0003 · 1 message on Pro · answered by deepseek/deepseek-v4.1-flash via Together ·
The summarization prompts, and how they're scored
Rubric (graded). The grader model scores the reply from 1 to 5 on each published criterion. It passes with an average of 4 or more and no criterion under 3, and only if it also meets the prompt's automatic rules (length, words it must or mustn't use).
The grader is Claude Opus 5.5 at low reasoning effort; its own replies are graded by GPT-6 Astra, so no model grades itself. Its prompt and every rubric are on the methods page.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five summarization prompts and how every reply was scored.
Prompts like these to try yourself
What matters for summarization
How much it can read
A model can only summarize what fits in its context window, listed for each model below.
Staying faithful
A summary is only useful if it's faithful. Ask for key numbers and quotes so you can check them.
The right length
Say who the summary is for and how long it should be; a one-line TL;DR and a one-page brief are different jobs.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | 1 message | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | Yes | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | Yes | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Summarization in llmwise
Attach your documents
Attach PDFs (up to 100 pages), images, Word, Excel, and PowerPoint files, and text or code files (plain text, Markdown, and CSV, JSON and more), up to 10 files a message.
Summarize a link
Paste a link and the model reads the page. It counts as one web search.
Keep the summary
Ask for the summary as a document to edit it, keep its versions and download it as PDF, Word or Markdown.
Long chats, stated up front
Past 64k tokens each reply counts as 2, past 128k as 4, and a chat stops at 200k; the composer says so before you send. One document per chat keeps it short.
Tips
Say who the summary is for and how long it should be.
Ask for the key numbers and quotes, with page references.
Ask what the summary leaves out.
Use one chat per long document.
Questions
What is the best AI for summarization?
In our test runs on October 9, 2026, 10 of the 19 models passed 5 of 5 summarization prompts, so these prompts don't name one best model. For best value, Gemini 3.8 Flash (5 of 5). For everyday, DeepSeek V4.1 Flash (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for summarization?
We sent the same summarization prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for summarization for free?
Yes, to try: Free is a one-time trial of 5 messages on every model but Claude Fable 5.1 and GPT-6 Astra (one of them can be on Claude Opus 5.5).
How long a document can I summarize?
PDFs up to 100 pages and files up to 20 MB, within the model's context window (listed below).
Does it matter which model reads my PDF?
A model that takes the whole PDF file receives the file itself. The others receive the text extracted from it, so a scanned PDF without a text layer gives them nothing to read.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.