Best AI · Translation
The best AI for translation
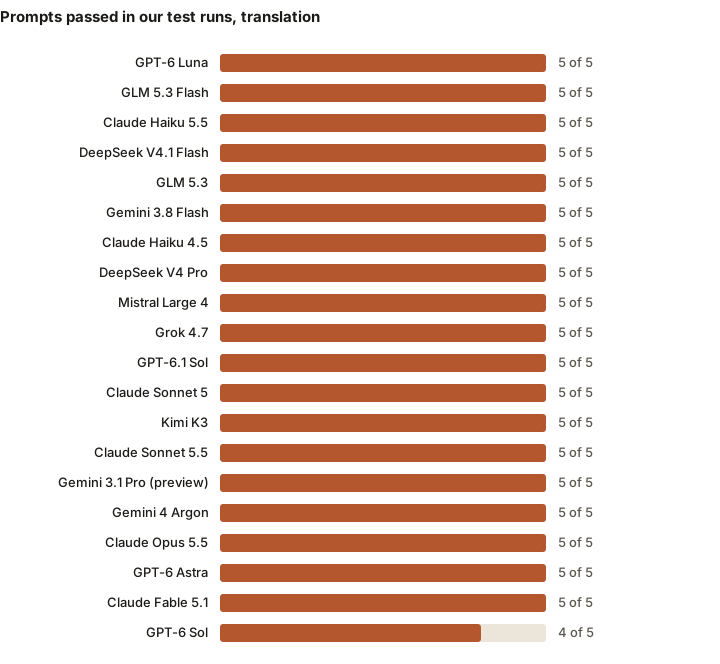
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 15, 2026, 19 of the 20 models passed 5 of 5 translation prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 100 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 15, 2026, 19 models passed 5 of 5 translation prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday translation, GPT-6 Luna (5 of 5), from the daily count.
Our picks for translation
Hard problems
Shared by 19 models
19 models passed 5 of 5, both hard ones: Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5 and 16 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 translation prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 translation prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 20 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our translation test runs, model by model
How each model did on our 5 translation prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0175 | 5.6 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0108 | 5.9 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0042 | 2.6 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0030 | 3.2 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 1.7 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0015 | 2.3 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0126 | 4.2 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0013 | 3.2 s |
| GPT-6 SolOpenAI | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0028 | 3.5 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.7 s |
| Gemini 4 ArgonGoogle | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0012 | 4.3 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0140 | 10.4 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0007 | 3.1 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0006 | 1.4 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0020 | 6.7 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0082 | 13.8 s |
| Kimi K3Moonshot | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0036 | 5.3 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0007 | 1.6 s |
| GLM 5.3 FlashZ.ai | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 3.7 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0031 | 16.8 s |
One prompt, side by side
Each model's reply to “Idioms into natural Japanese”, as it came, with whether it passed and what it cost.
The prompt: Idioms into natural Japanese (hard)
Translate this into natural Japanese for a business email. Convey what the idioms mean rather than translating them word for word, and keep the numbers.

Kenji, thanks for jumping in at the last minute. The new hire hit the ground running, so we're ahead of schedule. Can you give me a ballpark figure for the Osaka launch budget by the 20th? No need to boil the ocean: a rough number within 10% is fine.
Claude Fable 5.1
Passed: Back-translation chrF 0.51 (pass at 0.4).
健二さん

急なお願いにもかかわらず、直前で対応いただきありがとうございました。新しく入ったメンバーが早速戦力になってくれており、予定より前倒しで進んでいます。

大阪でのローンチ予算について、20日までに概算をいただけますでしょうか。細かく詰めていただく必要はなく、±10%程度の大まかな数字で結構です。

よろしくお願いいたします。

---

**Idiom handling notes:**
- "jumping in at the last minute" → 急なお願い/直前で対応 (stepping in on short notice)
- "hit the ground running" → 早速戦力になってくれて (became productive right away)
- "ballpark figure" → 概算 (rough estimate)
- "boil the ocean" → 細かく詰めていただく必要はなく (no need to go into exhaustive detail)
596 tokens in, 288 out · 8.5 s · $0.0217 · 1 message on Pro · answered by anthropic/claude-fable-5.1 via Anthropic ·
GLM 5.3
Passed: Back-translation chrF 0.49 (pass at 0.4).
Kenjiさん

直前のお願いにもかかわらず、引き受けていただきありがとうございます。新入社員が期待以上に早く戦力になってくれたおかげで、現在予定より進んでいます。大阪ローンチの予算について、20日までに概算の数字をいただけますか?厳密な精度は求めていませんので、±10%程度の概略の数字で結構です。

よろしくお願いいたします。

---

主な意訳のポイント:
- "jumping in at the last minute" → 直前の依頼に応じてもらったことへのお礼として表現
- "hit the ground running" → 「期待以上に早く戦力になった」
- "boil the ocean" → 「厳密な精度は求めていない」と簡潔に言い換え
- "ballpark figure" → 「概算」
470 tokens in, 200 out (1 of them reasoning) · 1.7 s · $0.0012 · 1 message on Pro · answered by z-ai/glm-5.3 via Wafer ·
GPT-6 Luna
Passed: Back-translation chrF 0.55 (pass at 0.4).
健司さん、直前の依頼に対応してくれてありがとうございます。新しく入ったメンバーが早速活躍してくれたおかげで、予定より前倒しで進んでいます。20日までに、大阪でのローンチにかかる予算の概算を出してもらえますか。細部まで詰める必要はありません。10%以内の誤差であれば、大まかな金額で大丈夫です。
431 tokens in, 113 out · 1.6 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The translation prompts, and how they're scored
Back-translation. Automatic. The translation must keep every name and number, be in the language asked for, and read back close to the original: the grader model translates it back into English without seeing the original, and the result is compared with it by character overlap (chrF).
The grader is Claude Opus 5.5 at low reasoning effort; its own replies are graded by GPT-6 Astra, so no model grades itself. Its prompt and every rubric are on the methods page.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five translation prompts and how every reply was scored.
Prompts like these to try yourself
What matters for translation
Your language pair
Models differ most on less common languages. Test the pair you actually need.
Tone and register
Formal or casual, legal or friendly: say which, or the model picks for you.
Keeping the formatting
Headings, lists and tables should survive translation. Ask for the same structure back.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | No | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 4 ArgonGoogle | 62/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | No | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Translation in llmwise
Switch models mid-chat
Start on a cheaper model; if the answer isn't good enough, switch models in the same chat. The next model sees the whole conversation, so you don't paste anything twice.
Attach your documents
Attach PDFs (up to 100 pages), images, Word, Excel, and PowerPoint files, and text or code files (plain text, Markdown, and CSV, JSON and more), up to 10 files a message.
Translations as documents
Ask for the translation as a document to edit it and download it as PDF, Word or Markdown.
A persona for your glossary
Save your glossary and style rules in a persona, so every translation uses the same terms.
Tips
Say who will read the translation and how formal it should be.
Give a glossary for names and terms that must not change.
Ask for a back-translation to spot meaning that drifted.
Have a native speaker check anything public or legal.
Questions
What is the best AI for translation?
In our test runs on October 15, 2026, 19 of the 20 models passed 5 of 5 translation prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, GPT-6 Luna (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for translation?
We sent the same translation prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for translation for free?
Yes, to try: Free is a one-time trial of 5 messages on Claude Haiku 5.5.
Which languages can it translate?
llmwise doesn't limit languages; what a model handles well depends on how its maker trained it. For an important text, try two models on the same passage and compare.
Can it translate a whole document?
Yes: attach it (PDFs up to 100 pages) and ask for the translation as a document, which downloads as PDF, Word or Markdown. Very long documents are best done a section at a time.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.