Blog · September 24, 2026
Updated · By llmwise, AI-assisted.
Multi-model AI: why one model isn't enough
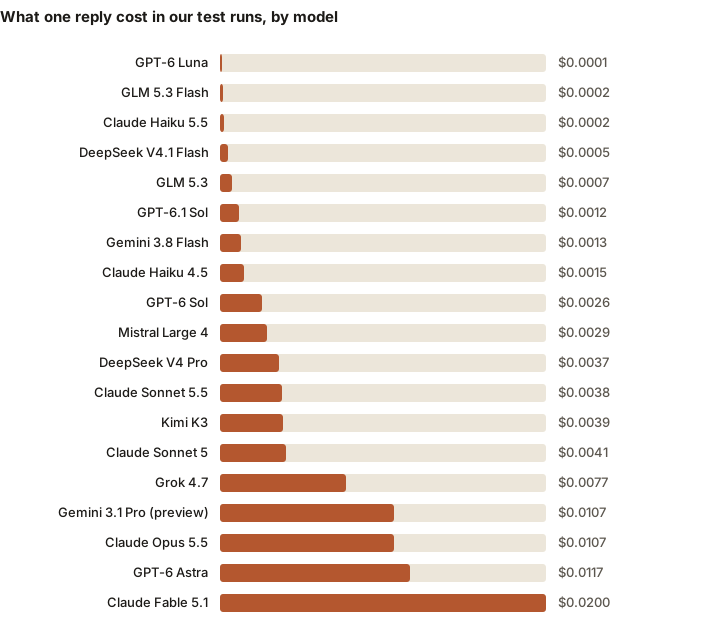
One model for everything costs more and catches less. A typical message on GPT-6 Astra costs about 100 times one on Claude Haiku 5.5, and context windows run from 200K tokens to 1.05M tokens. A cheap model for easy questions, a flagship for hard ones and a second family to check answers do better.
Models differ more than they look
Put the models in llmwise side by side and the spread is wide. At API prices as of October 2026, a typical message on GPT-6 Astra costs about 100 times one on Claude Haiku 5.5. Context windows run from 200K tokens to 1.05M tokens. DeepSeek V4 Pro and GLM 5.3 don't read images at all. Those differences are facts, not opinions, and they decide which model can do a job before quality even comes into it.
The makers publish them: Anthropic's models overview lists each Claude model's context window, and OpenAI's GPT-6 Astra page gives Astra's.
Different jobs want different models
Most of what people ask an AI is quick: a rewrite, a lookup, a formula. A fast, inexpensive model handles that well. Some of it is hard: a subtle bug, a contract, an analysis you'll present. That's where a flagship earns its price. Using one model for both means overpaying for the first kind or under-serving the second.
Our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026 put numbers on it. On every one of the 10 jobs, a model at a fraction of the price passed every prompt. GPT-6 Astra, the dearest model per message, missed at least one prompt on 1 of them.
| Job | Cheapest with full marks | Its cost per reply | GPT-6 Astra on the same prompts |
|---|---|---|---|
| Coding | GLM 5.3 Flash | $0.0003 | 5 of 5, $0.0223 a reply |
| Writing | GPT-6 Luna | $0.0001 | 5 of 5, $0.0111 a reply |
| Math | Claude Haiku 5.5 | $0.0001 | 5 of 5, $0.0085 a reply |
| Summarization | DeepSeek V4.1 Flash | $0.0002 | 5 of 5, $0.0109 a reply |
| Data analysis | GPT-6 Luna | $0.0002 | 5 of 5, $0.0154 a reply |
| Customer support | GLM 5.3 | $0.0005 | 3 of 5, $0.0116 a reply |
| Translation | GPT-6 Luna | $0.0001 | 5 of 5, $0.0126 a reply |
| SQL | GPT-6 Luna | $0.0001 | 5 of 5, $0.0098 a reply |
| RAG and answering from documents | GPT-6 Luna | $0.0001 | 5 of 5, $0.0079 a reply |
| Agents and tool use | GPT-6 Luna | $0.0001 | 5 of 5, $0.0068 a reply |
Cost per reply is what OpenRouter charged for our prompts, on average. The prompts and replies.
A second opinion catches mistakes
Models make mistakes, and they make different ones. When an answer matters, asking a model from another family is the cheapest check there is. If they agree, you're more confident; if they don't, you know where to look.
In our runs, 17 of the 50 prompts tripped at least one model: 69 failed replies in all. Every one of them was a prompt that a model from another family passed.
Models change, and providers have bad days
New versions arrive often, and a model that suited you last month may not be the best choice now. Providers also have outages, which their own status pages log (OpenAI's, Anthropic's). With more than one family to hand, neither stops your work: switch and carry on. (llmwise also reaches a model through OpenRouter when it can't reach the model's maker directly.)
The catch: switching has to be easy
Using several models only works if moving between them costs nothing. That's what llmwise is built around:
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral in one model picker.
Switch mid-chat: the next model sees the whole conversation, files included.
The picker shows how many messages you have left on each model, before you send.
The default model is an everyday one, so easy questions don't touch the monthly allowance unless you pick a bigger model.
We keep the list short on purpose: a few strong models from each family rather than hundreds. See which model to use when, or how to compare them on your own work.
Switch models without leaving the chat
llmwise has 19 models from every major family. The next one you pick sees the whole conversation.