Comparison
Claude vs ChatGPT
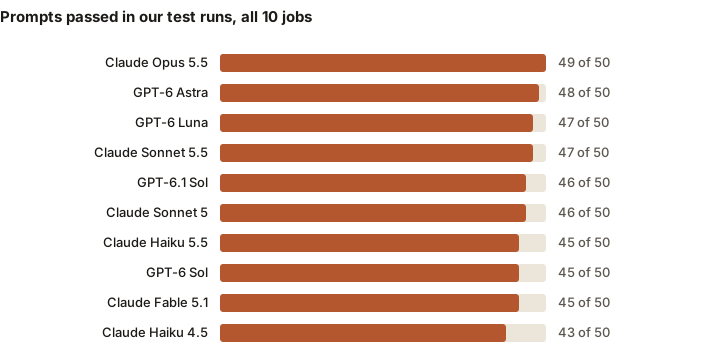
In our test runs on October 7, 2026, the same 50 prompts across 10 jobs: Claude's 6 models passed 275 of 300 replies and GPT's 4 models passed 186 of 200 replies. ChatGPT is OpenAI's own app for its GPT models; llmwise has GPT models in its own chat, not ChatGPT itself.
Based on 500 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
Job by job, both families' best models shared the top result on 8 of the 10 jobs; Claude's alone had it on customer support; GPT's alone had it on writing.
Claude vs GPT, job by job
On each job, Claude's pick against GPT's: the model of each family that passed the most of the job's 5 prompts (then the most hard ones, then the cheaper). The jobs where they differ most come first.
Writing: Claude Sonnet 5 passed 4 of 5 and GPT-6 Luna 5 of 5. GPT-6 Luna answered 1.9× sooner at the median, 4.5 s against 2.4 s. GPT-6 Luna cost 34.3× less, $0.0171 against $0.0005 for the 5 replies. Claude Sonnet 5's replies ran 115% longer, in tokens of reply, thinking not counted.
Customer support: Claude Sonnet 5 passed 5 of 5 and GPT-6 Luna 4 of 5. GPT-6 Luna answered 2.5× sooner at the median, 3.5 s against 1.4 s. GPT-6 Luna cost 42.1× less, $0.0182 against $0.0004 for the 5 replies. Claude Sonnet 5's replies ran 218% longer, in tokens of reply, thinking not counted.
Coding: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. Claude Haiku 5.5 answered 1.2× sooner at the median, 3.9 s against 4.6 s. GPT-6 Luna cost 1.6× less, $0.0023 against $0.0014 for the 5 replies. Claude Haiku 5.5's replies ran 71% longer, in tokens of reply, thinking not counted.
Math: Claude Haiku 5.5 passed 5 of 5 and GPT-6.1 Sol 5 of 5. Their median waits were close, 1.7 s against 1.8 s. Claude Haiku 5.5 cost 5.9× less, $0.0007 against $0.0043 for the 5 replies. Claude Haiku 5.5's replies ran 122% longer, in tokens of reply, thinking not counted.
Summarization: Claude Haiku 4.5 passed 5 of 5 and GPT-6.1 Sol 5 of 5. Claude Haiku 4.5 answered 1.2× sooner at the median, 1.7 s against 2.0 s. They cost about the same, $0.0051 against $0.0050 for the 5 replies. Their replies ran to about the same length.
Data analysis: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. GPT-6 Luna answered 1.3× sooner at the median, 3.3 s against 2.5 s. GPT-6 Luna cost 2.0× less, $0.0018 against $0.0009 for the 5 replies. Claude Haiku 5.5's replies ran 157% longer, in tokens of reply, thinking not counted.
Translation: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. Their median waits were close, 1.4 s against 1.6 s. GPT-6 Luna cost 1.9× less, $0.0009 against $0.0005 for the 5 replies. Claude Haiku 5.5's replies ran 115% longer, in tokens of reply, thinking not counted.
SQL: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. Their median waits were close, 1.3 s against 1.2 s. GPT-6 Luna cost 2.5× less, $0.0011 against $0.0004 for the 5 replies. Claude Haiku 5.5's replies ran 72% longer, in tokens of reply, thinking not counted.
RAG and answering from documents: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. Claude Haiku 5.5 answered 1.2× sooner at the median, 1.1 s against 1.3 s. GPT-6 Luna cost 1.8× less, $0.0007 against $0.0004 for the 5 replies. Claude Haiku 5.5's replies ran 139% longer, in tokens of reply, thinking not counted.
Agents and tool use: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. Claude Haiku 5.5 answered 1.8× sooner at the median, 1.0 s against 1.9 s. GPT-6 Luna cost 1.7× less, $0.0007 against $0.0004 for the 5 replies. Claude Haiku 5.5's replies ran 59% longer, in tokens of reply, thinking not counted.
The 2 prompts only one of Claude and GPT passed
Where one family's pick passed a prompt and the other's didn't, in each check's own words.
Announce a second bakery shop on LinkedIn (writing): GPT-6 Luna passed and Claude Sonnet 5 didn't. Claude Sonnet 5: Graded 3.5 of 5 on average (lowest 3). GPT-6 Luna: Graded 4.5 of 5 on average (lowest 4).
A frustrated customer (customer support): Claude Sonnet 5 passed and GPT-6 Luna didn't. Claude Sonnet 5: Graded 4.3 of 5 on average (lowest 4). GPT-6 Luna: Graded 3.0 of 5 on average (lowest 2).
Each Claude model against each GPT model
Every Claude model against every GPT model on the same 50 prompts: each one's passes, how many prompts split them, and who was cheaper and quicker.
Claude Fable 5.1 vs GPT-6 Astra: 45 and 48 of 50; 7 prompts split them; GPT-6 Astra's replies cost 1.7× less in all, and GPT-6 Astra answered sooner on 42, Claude Fable 5.1 on 3. Claude Fable 5.1 vs GPT-6 Astra.
Claude Fable 5.1 vs GPT-6.1 Sol: 45 and 46 of 50; 9 prompts split them; GPT-6.1 Sol's replies cost 16.8× less in all, and GPT-6.1 Sol answered sooner on 48, Claude Fable 5.1 on 0.
Claude Fable 5.1 vs GPT-6 Sol: 45 and 45 of 50; 8 prompts split them; GPT-6 Sol's replies cost 7.7× less in all, and GPT-6 Sol answered sooner on 48, Claude Fable 5.1 on 0.
Claude Fable 5.1 vs GPT-6 Luna: 45 and 47 of 50; 6 prompts split them; GPT-6 Luna's replies cost 169.8× less in all, and GPT-6 Luna answered sooner on 49, Claude Fable 5.1 on 0.
Claude Opus 5.5 vs GPT-6 Astra: 49 and 48 of 50; 3 prompts split them; their replies cost about the same in all, and GPT-6 Astra answered sooner on 45, Claude Opus 5.5 on 4. Claude Opus 5.5 vs GPT-6 Astra.
Claude Opus 5.5 vs GPT-6.1 Sol: 49 and 46 of 50; 5 prompts split them; GPT-6.1 Sol's replies cost 9.0× less in all, and GPT-6.1 Sol answered sooner on 48, Claude Opus 5.5 on 0.
Claude Opus 5.5 vs GPT-6 Sol: 49 and 45 of 50; 6 prompts split them; GPT-6 Sol's replies cost 4.1× less in all, and GPT-6 Sol answered sooner on 45, Claude Opus 5.5 on 0. Claude Opus 5.5 vs GPT-6 Sol.
Claude Opus 5.5 vs GPT-6 Luna: 49 and 47 of 50; 4 prompts split them; GPT-6 Luna's replies cost 90.8× less in all, and GPT-6 Luna answered sooner on 49, Claude Opus 5.5 on 1.
Claude Sonnet 5.5 vs GPT-6 Astra: 47 and 48 of 50; 3 prompts split them; Claude Sonnet 5.5's replies cost 3.1× less in all, and Claude Sonnet 5.5 answered sooner on 42, GPT-6 Astra on 3.
Claude Sonnet 5.5 vs GPT-6.1 Sol: 47 and 46 of 50; 5 prompts split them; GPT-6.1 Sol's replies cost 3.2× less in all, and Claude Sonnet 5.5 answered sooner on 26, GPT-6.1 Sol on 11. GPT-6.1 Sol vs Claude Sonnet 5.5.
Claude Sonnet 5.5 vs GPT-6 Sol: 47 and 45 of 50; 6 prompts split them; GPT-6 Sol's replies cost 1.5× less in all, and Claude Sonnet 5.5 answered sooner on 30, GPT-6 Sol on 15. Claude Sonnet 5.5 vs GPT-6 Sol.
Claude Sonnet 5.5 vs GPT-6 Luna: 47 and 47 of 50; 4 prompts split them; GPT-6 Luna's replies cost 32.4× less in all, and GPT-6 Luna answered sooner on 25, Claude Sonnet 5.5 on 18.
Claude Sonnet 5 vs GPT-6 Astra: 46 and 48 of 50; 6 prompts split them; Claude Sonnet 5's replies cost 2.9× less in all, and GPT-6 Astra answered sooner on 27, Claude Sonnet 5 on 15.
Claude Sonnet 5 vs GPT-6.1 Sol: 46 and 46 of 50; 8 prompts split them; GPT-6.1 Sol's replies cost 3.4× less in all, and GPT-6.1 Sol answered sooner on 40, Claude Sonnet 5 on 7.
Claude Sonnet 5 vs GPT-6 Sol: 46 and 45 of 50; 7 prompts split them; GPT-6 Sol's replies cost 1.6× less in all, and GPT-6 Sol answered sooner on 35, Claude Sonnet 5 on 10. Claude Sonnet 5 vs GPT-6 Sol.
Claude Sonnet 5 vs GPT-6 Luna: 46 and 47 of 50; 5 prompts split them; GPT-6 Luna's replies cost 34.4× less in all, and GPT-6 Luna answered sooner on 42, Claude Sonnet 5 on 5.
Claude Haiku 4.5 vs GPT-6 Astra: 43 and 48 of 50; 7 prompts split them; Claude Haiku 4.5's replies cost 7.9× less in all, and Claude Haiku 4.5 answered sooner on 41, GPT-6 Astra on 4.
Claude Haiku 4.5 vs GPT-6.1 Sol: 43 and 46 of 50; 9 prompts split them; GPT-6.1 Sol's replies cost 1.2× less in all, and Claude Haiku 4.5 answered sooner on 30, GPT-6.1 Sol on 10.
Claude Haiku 4.5 vs GPT-6 Sol: 43 and 45 of 50; 10 prompts split them; Claude Haiku 4.5's replies cost 1.7× less in all, and Claude Haiku 4.5 answered sooner on 30, GPT-6 Sol on 12. Claude Haiku 4.5 vs GPT-6 Sol.
Claude Haiku 4.5 vs GPT-6 Luna: 43 and 47 of 50; 8 prompts split them; GPT-6 Luna's replies cost 12.6× less in all, and GPT-6 Luna answered sooner on 21, Claude Haiku 4.5 on 20. Claude Haiku 4.5 vs GPT-6 Luna.
Claude Haiku 5.5 vs GPT-6 Astra: 45 and 48 of 50; 5 prompts split them; Claude Haiku 5.5's replies cost 49.8× less in all, and Claude Haiku 5.5 answered sooner on 43, GPT-6 Astra on 5.
Claude Haiku 5.5 vs GPT-6.1 Sol: 45 and 46 of 50; 5 prompts split them; Claude Haiku 5.5's replies cost 5.1× less in all, and Claude Haiku 5.5 answered sooner on 39, GPT-6.1 Sol on 8.
Claude Haiku 5.5 vs GPT-6 Sol: 45 and 45 of 50; 4 prompts split them; Claude Haiku 5.5's replies cost 11.0× less in all, and Claude Haiku 5.5 answered sooner on 31, GPT-6 Sol on 8.
Claude Haiku 5.5 vs GPT-6 Luna: 45 and 47 of 50; 4 prompts split them; GPT-6 Luna's replies cost 2.0× less in all, and GPT-6 Luna answered sooner on 20, Claude Haiku 5.5 on 17. Claude Haiku 5.5 vs GPT-6 Luna.
One writing prompt, both replies
Claude Sonnet 5 and GPT-6 Luna on a writing prompt, the job where they differed most: both replies as they came.
An everyday prompt: “Announce a second bakery shop on LinkedIn”, in full.
Claude Sonnet 5
Failed: Graded 3.5 of 5 on average (lowest 3).
We have some exciting news to share: Crumb & Co. is opening our second shop, this time in Leeds!

From our very first bakery, we've believed in doing simple things well — proper sourdough, honest pastries, and coffee worth stopping for. Now we get to bring that same spirit to a new neighbourhood and, hopefully, a whole new group of familiar faces.

Our Leeds shop opens its doors on 14 November, and we'd love for you to be there. To celebrate, every coffee on opening day is on us — no catch, just our way of saying thank you for supporting us along the way.

This has been months of planning, a lot of taste-testing, and more excitement than we know what to do with. We can't wait to welcome you in, share some fresh bakes, and start building new memories together.

See you there — first coffee's on the house.
538 tokens in, 267 out · 4.6 s · $0.0037 · 1 message on Pro · answered by anthropic/claude-sonnet-5 via Claude Platform on AWS ·
GPT-6 Luna
Passed: Graded 4.5 of 5 on average (lowest 4).
We’re delighted to share that Crumb & Co. is opening a second shop in Leeds on 14 November!

What began as one small bakery has grown thanks to the lovely people who’ve stopped by, shared a loaf, and made us feel part of the community. We’re excited to bring our freshly baked bread, pastries, and warm welcomes to a new neighbourhood.

To celebrate opening day, we’ll be giving away free coffee. Pop in, say hello, and enjoy a cup with us—we’d love to meet you.

Thank you to everyone who has supported Crumb & Co. so far. We can’t wait to open the doors and start this next chapter together. See you in Leeds on 14 November!
389 tokens in, 149 out · 2.9 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Every model, every job
All 10 Claude and GPT models in llmwise across the 50 prompts, with what a reply cost to run and each model's count on Pro.
| Model | Passed | Hard ones | Cost per reply | On Pro |
|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 45 of 50 | 17 of 20 | $0.0200 | Up to 31 a month |
| Claude Opus 5.5Anthropic | 49 of 50 | 19 of 20 | $0.0107 | Up to 62 a month |
| Claude Sonnet 5.5Anthropic | 47 of 50 | 19 of 20 | $0.0038 | Up to 125 a month |
| Claude Sonnet 5Anthropic | 46 of 50 | 19 of 20 | $0.0041 | Up to 125 a month |
| Claude Haiku 4.5Anthropic | 43 of 50 | 15 of 20 | $0.0015 | Up to 250 a month |
| Claude Haiku 5.5Anthropic | 45 of 50 | 19 of 20 | $0.00024 | Up to 60 a day |
| GPT-6 AstraOpenAI | 48 of 50 | 20 of 20 | $0.0117 | Up to 31 a month |
| GPT-6.1 SolOpenAI | 46 of 50 | 19 of 20 | $0.0012 | Up to 125 a month |
| GPT-6 SolOpenAI | 45 of 50 | 19 of 20 | $0.0026 | Up to 125 a month |
| GPT-6 LunaOpenAI | 47 of 50 | 20 of 20 | $0.00012 | Up to 60 a day |
Passed: replies that passed their check, of those scored. Cost: what OpenRouter charged us per reply, on average; in llmwise you pay per message, not per token. Every prompt and how it's scored.
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Their own subscriptions
Each company's own plan at about llmwise Pro's price ($20 a month), in its own words, dated. We drop a plan here when its facts are more than 45 days old.
Claude Pro (Anthropic), $20 a month
Models it names: Claude Opus, Claude Sonnet, and Claude Haiku. On its limits: “The number of messages you can send will vary based on message length, including the length of files you attach, the length of your current conversation, and the model or feature you use. Your session-based usage limit will reset every five hours.” Claude Pro vs llmwise.
Checked : Claude Help Center: What is the Pro plan?, Claude Help Center: Claude Fable models on your plan and Claude pricing.
ChatGPT Plus (OpenAI), $20 a month
Models it names: GPT-6 Astra, GPT-6 Sol, and GPT-6 Luna. On its limits: “To ensure a smooth experience for all users, Plus subscriptions may include usage limits such as message caps, especially during high demand. These limits may vary based on system conditions.” ChatGPT Plus vs llmwise.
Checked : OpenAI Help Center: What is ChatGPT Plus?, OpenAI Help Center: Managing usage with GPT-6 Astra in Work and Codex and ChatGPT pricing.
llmwise Pro, $20 a month, has all 10 of these models in one chat, on one monthly allowance. On it: Claude Sonnet 5.5 up to 125 messages a month and GPT-6.1 Sol up to 125.
The lineups at a glance
What follows from each model's facts in our catalog.
The lineups
Claude: 6 models, Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5, Claude Sonnet 5, Claude Haiku 4.5, and Claude Haiku 5.5. GPT: 4 models, GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, and GPT-6 Luna.
Price per message
The least expensive Claude model is Claude Haiku 5.5 (60 messages a day on Pro); the least expensive GPT model is GPT-6 Luna (60 messages a day on Pro).
Context window
Claude goes up to 1M tokens (Claude Fable 5.1); GPT up to 1.05M tokens (GPT-6 Astra).
Images and PDFs
Every model here reads images. Every model here takes a PDF as a whole file.
On the Free plan
Free's one-time trial of 5 messages covers Claude Sonnet 5.5, Claude Sonnet 5, Claude Haiku 4.5, Claude Haiku 5.5, GPT-6.1 Sol, GPT-6 Sol, and GPT-6 Luna, and Claude Opus 5.5 for 1 message. Paid plans have every model, with messages every month.
Model by model
Two named models side by side, prompt by prompt, each with its messages on every plan.
More head-to-heads
Each of Claude and GPT against the other families, every job from the same test runs.
Where your messages go
In llmwise, a message to Claude or GPT goes to the model's maker, or through OpenRouter when llmwise can't reach the maker directly. The Privacy Policy has the details.
GPT or Claude: what people ask
Which is better, Claude or ChatGPT?
In our test runs on October 7, 2026, the same 50 prompts across 10 jobs: Claude's 6 models passed 275 of 300 replies and GPT's 4 models passed 186 of 200 replies. Job by job, both families' best models shared the top result on 8 of the 10 jobs; Claude's alone had it on customer support; GPT's alone had it on writing.
Which is cheaper, Claude or GPT?
In llmwise, the least expensive Claude model is Claude Haiku 5.5 (60 messages a day on Pro), and the least expensive GPT model is GPT-6 Luna (60 messages a day on Pro). At API list prices (October 2026), a typical message of 4,000 tokens in and 700 out costs $0.0008 on Claude Haiku 5.5 and $0.0008 on GPT-6 Luna.
Can I use Claude and GPT in the same chat?
Yes. Pick a model for each message; when you switch, the next model sees the whole conversation, including the other one's answers.
Settle it on your own question
Ask Claude Opus 5.5 (up to 62 a month on Pro), then switch the picker to GPT-6 Astra (up to 31 a month) and ask again. The second sees the first's answer.