Best AI · Agents and tool use
The best AI for agents and tool use
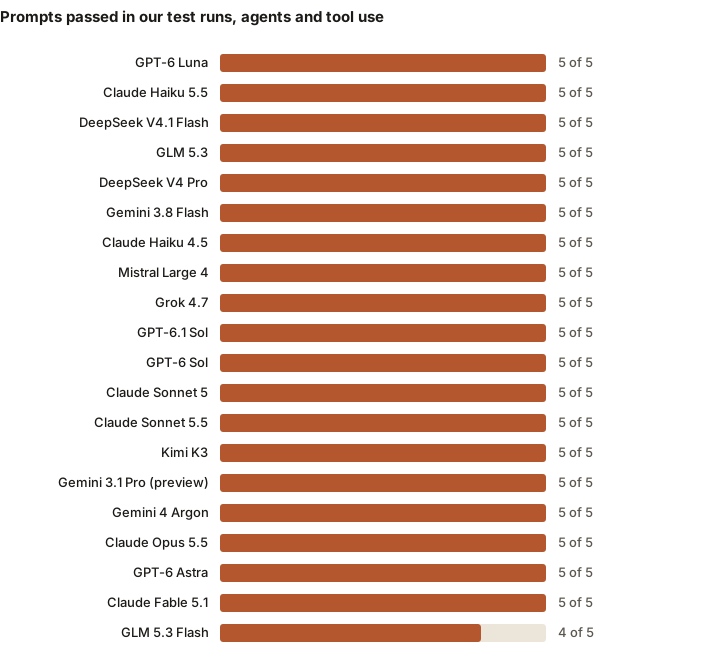
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 15, 2026, 19 of the 20 models passed 5 of 5 agents and tool use prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 100 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 15, 2026, 19 models passed 5 of 5 agents and tool use prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday agents and tool use, GPT-6 Luna (5 of 5), from the daily count.
Our picks for agents and tool use
Hard problems
Shared by 19 models
19 models passed 5 of 5, both hard ones: Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5 and 16 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 agents and tool use prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 agents and tool use prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 20 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our agents and tool use test runs, model by model
How each model did on our 5 agents and tool use prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0119 | 3.8 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0050 | 3.8 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0026 | 1.8 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0024 | 3.0 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.6 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0009 | 1.1 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0068 | 2.0 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0007 | 1.6 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0016 | 1.9 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.7 s |
| Gemini 4 ArgonGoogle | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0011 | 3.9 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0057 | 5.7 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0009 | 4.6 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 0.5 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0007 | 2.0 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0039 | 6.1 s |
| Kimi K3Moonshot | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0027 | 2.4 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0004 | 1.0 s |
| GLM 5.3 FlashZ.ai | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 3.7 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0013 | 5.6 s |
One prompt, side by side
Each model's reply to “Search, but don't book”, as it came, with whether it passed and what it cost.
The prompt: Search, but don't book (hard)
You can call these tools:
- search_flights(origin: string, destination: string, date: string in YYYY-MM-DD, max_stops: number): searches flights between airports given as IATA codes, like "LHR".
- book_flight(flight_id: string): books a flight found by a search.

Today is Monday, 5 October 2026.
User: Find me nonstop flights from Boston to Denver on November 14. Don't book anything yet: I want to see the options first.

Reply with only a JSON object, {"calls": [{"tool": "<name>", "arguments": {...}}]}, listing the tool calls to make now. If no call is right yet, reply {"calls": []}.
Claude Fable 5.1
Passed: Made the 1 expected call.
{"calls": [{"tool": "search_flights", "arguments": {"origin": "BOS", "destination": "DEN", "date": "2026-11-14", "max_stops": 0}}]}677 tokens in, 66 out · 5.0 s · $0.0116 · 1 message on Pro · answered by anthropic/claude-fable-5.1 via Anthropic ·
GLM 5.3
Passed: Made the 1 expected call.
{"calls":[{"tool":"search_flights","arguments":{"origin":"BOS","destination":"DEN","date":"2026-11-14","max_stops":0}}]}527 tokens in, 38 out (1 of them reasoning) · 0.5 s · $0.0005 · 1 message on Pro · answered by z-ai/glm-5.3 via Wafer ·
GPT-6 Luna
Passed: Made the 1 expected call.
{"calls":[{"tool":"search_flights","arguments":{"origin":"BOS","destination":"DEN","date":"2026-11-14","max_stops":0}}]}487 tokens in, 72 out (29 of them reasoning) · 2.2 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The agents and tool use prompts, and how they're scored
Tool calls. Automatic. The reply's JSON must make exactly the right tool calls, with the right arguments, and no others.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five agents and tool use prompts and how every reply was scored.
Prompts like these to try yourself
What matters for agents and tool use
Reliable tool calls
An agentic task is only as good as the model's tool calls: picking the right tool, passing sensible inputs, and reading the result before the next step.
Following a plan
Multi-step work needs a model that keeps the goal and your constraints in mind across many steps, and stops when it's done.
Knowing when to ask
A good agent asks when a step is risky or the goal is unclear, instead of guessing.
Room for tool output
Every step reads the conversation again, so a model with a large context window has more room for long tool outputs.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | No | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 4 ArgonGoogle | 62/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | No | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | No | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | No | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Agents and tool use in llmwise
Web search with sources
The model can search the web and cite what it found as source cards, or read a link you paste. On Free, web search works inside your 5 trial messages; on a paid plan a search counts as one more message of the model in use.
Run code (Pro and higher plans)
On Pro and higher plans the model can run Python or Node.js in an isolated sandbox once you approve it, read the output and fix what failed. A run counts as 1 Claude Haiku 4.5 message and stops after 60 seconds.
MCP servers (Pro and higher plans)
On Pro and higher plans, connect MCP servers to give the model extra tools, yours or the ones we set up. Each tool call waits for your approval unless you choose Always allow.
Skills
Save instructions and reference files as a skill; the model reads the files it needs when a task calls for them.
Tips
State the goal, the constraints and what done looks like before the model starts.
Ask for a short plan first, then let it work through the steps.
Approve code runs one at a time until you trust the pattern, then use Always allow.
Ask it to show the sources or the output it relied on for each conclusion.
Questions
What is the best AI for agents and tool use?
In our test runs on October 15, 2026, 19 of the 20 models passed 5 of 5 agents and tool use prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, GPT-6 Luna (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for agents and tool use?
We sent the same agents and tool use prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for agents and tool use for free?
Yes, to try: Free is a one-time trial of 5 messages on Claude Haiku 5.5.
Does one message cover every tool step?
The message's price covers the whole reply, however many steps it takes. Paid tools add their own price on top: on a paid plan a web search counts as one more message of the model in use, a code run counts as 1 Claude Haiku 4.5 message, an image from 2 Claude Haiku 4.5 messages an image (by image model), a backend app 5 Claude Haiku 4.5 messages per started 10 minutes, and a research report 15 Claude Haiku 4.5 messages (Standard) or 75 Claude Haiku 4.5 messages (Deep). Code runs, backend apps, research reports and MCP tools ask for your approval first.
Can I build and deploy an agent with llmwise?
No. llmwise is a chat app: the model works through tools inside a reply, with you watching and approving. There's no API, scheduler or background agent.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.