Comparison
Grok vs Kimi
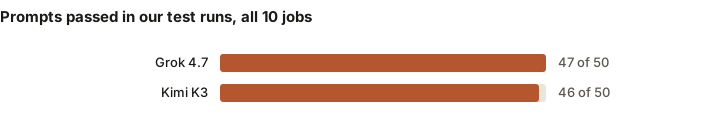
In our test runs on October 2, 2026, the same 50 prompts across 10 jobs: Grok's one model passed 47 of 50 replies and Kimi's one model passed 46 of 50 replies. On llmwise Pro, Grok 4.7 up to 250 messages a month and Kimi K3 up to 125.
Based on 100 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
Job by job, both families' best models shared the top result on 8 of the 10 jobs; Grok's alone had it on summarization; Kimi's alone had it on writing.
Grok vs Kimi, job by job
On each job, Grok's pick against Kimi's: the model of each family that passed the most of the job's 5 prompts (then the most hard ones, then the cheaper). The jobs where they differ most come first.
Summarization: Grok 4.7 passed 5 of 5 and Kimi K3 3 of 5. Grok 4.7 answered 1.2× sooner at the median, 2.8 s against 3.4 s. Grok 4.7 cost 1.2× less, $0.0141 against $0.0172 for the 5 replies. Kimi K3's replies ran 27% longer, in tokens of reply, thinking not counted.
Writing: Grok 4.7 passed 3 of 5 and Kimi K3 4 of 5. Kimi K3 answered 2.0× sooner at the median, 6.0 s against 3.0 s. Kimi K3 cost 1.5× less, $0.0288 against $0.0192 for the 5 replies. Kimi K3's replies ran 27% longer, in tokens of reply, thinking not counted.
Coding: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 7.6× sooner at the median, 31.6 s against 4.1 s. Kimi K3 cost 3.9× less, $0.1229 against $0.0316 for the 5 replies. Their replies ran to about the same length.
Math: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 2.2× sooner at the median, 11.7 s against 5.4 s. Kimi K3 cost 1.9× less, $0.0362 against $0.0187 for the 5 replies. Grok 4.7's replies ran 65% longer, in tokens of reply, thinking not counted.
Data analysis: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 2.5× sooner at the median, 8.9 s against 3.5 s. Kimi K3 cost 1.6× less, $0.0556 against $0.0339 for the 5 replies. Kimi K3's replies ran 38% longer, in tokens of reply, thinking not counted.
Customer support: Grok 4.7 passed 4 of 5 and Kimi K3 4 of 5. Kimi K3 answered 2.7× sooner at the median, 11.6 s against 4.3 s. Kimi K3 cost 1.3× less, $0.0306 against $0.0228 for the 5 replies. Kimi K3's replies ran 42% longer, in tokens of reply, thinking not counted.
Translation: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 2.1× sooner at the median, 10.7 s against 5.2 s. Kimi K3 cost 2.3× less, $0.0410 against $0.0179 for the 5 replies. Kimi K3's replies ran 130% longer, in tokens of reply, thinking not counted.
SQL: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 1.9× sooner at the median, 3.0 s against 1.6 s. Kimi K3 cost 2.0× less, $0.0240 against $0.0118 for the 5 replies. Kimi K3's replies ran 15% longer, in tokens of reply, thinking not counted.
RAG and answering from documents: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Grok 4.7 answered 1.4× sooner at the median, 1.9 s against 2.6 s. Kimi K3 cost 2.0× less, $0.0146 against $0.0073 for the 5 replies. Kimi K3's replies ran 99% longer, in tokens of reply, thinking not counted.
Agents and tool use: Grok 4.7 passed 5 of 5 and Kimi K3 5 of 5. Kimi K3 answered 2.6× sooner at the median, 5.2 s against 2.0 s. Kimi K3 cost 1.5× less, $0.0197 against $0.0135 for the 5 replies. Kimi K3's replies ran 24% longer, in tokens of reply, thinking not counted.
The 7 prompts only one of Grok and Kimi passed
Where one family's pick passed a prompt and the other's didn't, in each check's own words.
An article in three bullets (summarization): Grok 4.7 passed and Kimi K3 didn't. Grok 4.7: Graded 4.7 of 5 on average (lowest 4). Kimi K3: Graded 4.0 of 5 on average (lowest 3); but 62 words, over the 60 allowed.
An email thread in one sentence (summarization): Grok 4.7 passed and Kimi K3 didn't. Grok 4.7: Graded 4.7 of 5 on average (lowest 4). Kimi K3: Graded 5.0 of 5 on average (lowest 5); but 32 words, over the 30 allowed.
Rewrite corporate jargon in plain words (writing): Kimi K3 passed and Grok 4.7 didn't. Grok 4.7: Graded 3.7 of 5 on average (lowest 3). Kimi K3: Graded 4.3 of 5 on average (lowest 4).
A product announcement with five rules (writing): Grok 4.7 passed and Kimi K3 didn't. Grok 4.7: Graded 4.0 of 5 on average (lowest 3). Kimi K3: Graded 4.3 of 5 on average (lowest 4); but doesn't end with a question.
Argue both sides of free buses (writing): Kimi K3 passed and Grok 4.7 didn't. Grok 4.7: Graded 4.7 of 5 on average (lowest 4); but a paragraph of 100 words, over the 90 allowed. Kimi K3: Graded 4.7 of 5 on average (lowest 4).
A frustrated customer (customer support): Kimi K3 passed and Grok 4.7 didn't. Grok 4.7: Graded 3.7 of 5 on average (lowest 3). Kimi K3: Graded 4.0 of 5 on average (lowest 3).
A refund request outside the window (customer support): Grok 4.7 passed and Kimi K3 didn't. Grok 4.7: Graded 4.0 of 5 on average (lowest 3). Kimi K3: Graded 4.0 of 5 on average (lowest 2).
One summarization prompt, both replies
Grok 4.7 and Kimi K3 on a summarization prompt, the job where they differed most: both replies as they came.
An everyday prompt: “An article in three bullets”, in full.
Grok 4.7
Passed: Graded 4.7 of 5 on average (lowest 4).
- Aldmoor’s six-month Market Street bike-lane trial ends; the council votes in November on making them permanent.
- Daily bike trips rose from about 900 to 2,300; car traffic fell 14%, with rush-hour delays of just over a minute.
- Businesses were split; cyclist injuries fell from nine to two; permanence would add €1.1 million to the €410,000 install cost.
1,759 tokens in, 115 out (25 of them reasoning) · 2.6 s · $0.0025 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
Kimi K3
Failed: Graded 4.0 of 5 on average (lowest 3); but 62 words, over the 60 allowed.
- Aldmoor's six-month protected bike lane trial on Market Street ended; the council votes in November on making them permanent.
- Bike trips rose from 900 to 2,300 daily, cyclist injuries dropped from nine to two, while car traffic fell 14% with only slightly longer rush-hour drive times.
- Businesses were split on customer impact; installation cost €410,000, with permanent lanes requiring €1.1 million more.
608 tokens in, 109 out (10 of them reasoning) · 2.8 s · $0.0028 · 1 message on Pro · answered by moonshotai/kimi-k3 via Phala ·
Every model, every job
All 2 Grok and Kimi models in llmwise across the 50 prompts, with what a reply cost to run and each model's count on Pro.
| Model | Passed | Hard ones | Cost per reply | On Pro |
|---|---|---|---|---|
| Grok 4.7xAI | 47 of 50 | 19 of 20 | $0.0077 | Up to 250 a month |
| Kimi K3Moonshot | 46 of 50 | 18 of 20 | $0.0039 | Up to 125 a month |
Passed: replies that passed their check, of those scored. Cost: what OpenRouter charged us per reply, on average; in llmwise you pay per message, not per token. Every prompt and how it's scored.
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Its own subscription
The one company here with its own plan at about llmwise Pro's price ($20 a month), in its own words, dated. We drop a plan here when its facts are more than 45 days old.
SuperGrok (SpaceXAI), $30 a month
Models it names: Grok 4.6. On its limits: “Smarter answers in Expert mode: Access our best model with higher limits” SuperGrok vs llmwise.
Checked : Grok plans.
llmwise Pro, $20 a month, has all 2 of these models in one chat, on one monthly allowance. On it: Grok 4.7 up to 250 messages a month and Kimi K3 up to 125.
The lineups at a glance
What follows from each model's facts in our catalog.
The lineups
Grok: one model, Grok 4.7. Kimi: one model, Kimi K3.
Price per message
Grok's one model is Grok 4.7 (250 messages a month on Pro); Kimi's one model is Kimi K3 (125 messages a month on Pro).
Context window
Grok goes up to 500K tokens (Grok 4.7); Kimi up to 1.05M tokens (Kimi K3).
Images and PDFs
Every model here reads images. Kimi K3 gets a PDF's text rather than the file itself.
On the Free plan
None of these models is on the Free plan. Paid plans have them all, with messages every month.
Model by model
Two named models side by side, prompt by prompt, each with its messages on every plan.
More head-to-heads
Each of Grok and Kimi against the other families, every job from the same test runs.
Where your messages go
Grok and Kimi models are served only through OpenRouter, by endpoints that don't store or train on prompts. The Privacy Policy has the details.
Questions
Which is better, Grok or Kimi?
In our test runs on October 2, 2026, the same 50 prompts across 10 jobs: Grok's one model passed 47 of 50 replies and Kimi's one model passed 46 of 50 replies. Job by job, both families' best models shared the top result on 8 of the 10 jobs; Grok's alone had it on summarization; Kimi's alone had it on writing.
Which is cheaper, Grok or Kimi?
In llmwise, the least expensive Grok model is Grok 4.7 (250 messages a month on Pro), and the least expensive Kimi model is Kimi K3 (125 messages a month on Pro). At API list prices (October 2026), a typical message of 4,000 tokens in and 700 out costs $0.0122 on Grok 4.7 and $0.0225 on Kimi K3.
Can I use Grok and Kimi in the same chat?
Yes. Pick a model for each message; when you switch, the next model sees the whole conversation, including the other one's answers.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.