Best AI · Writing
The best AI for writing
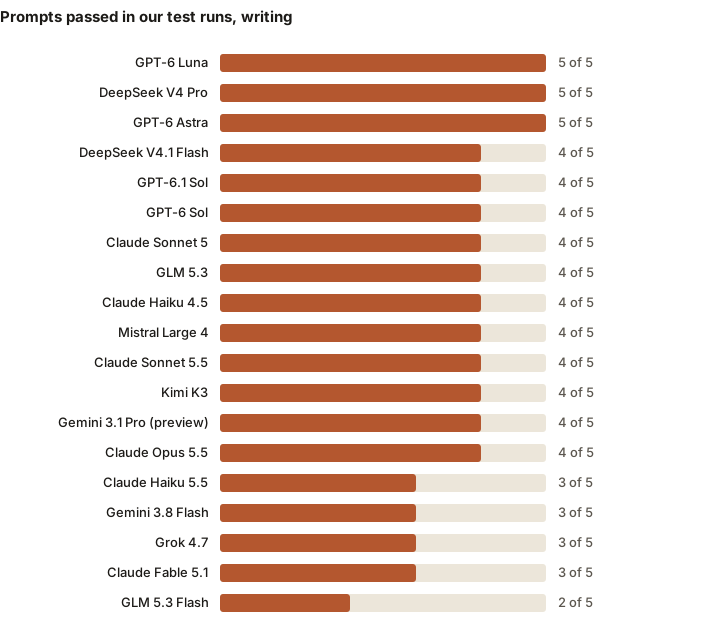
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026, 3 of the 19 models passed 5 of 5 writing prompts, so these prompts don't name one best model. For best value, DeepSeek V4 Pro (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 95 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 9, 2026, 3 models passed 5 of 5 writing prompts, so these prompts don't pick one for hard problems. For value, DeepSeek V4 Pro (5 of 5), 250 a month on Pro; for everyday writing, GPT-6 Luna (5 of 5), from the daily count.
Our picks for writing
Hard problems
Shared by 3 models
3 models passed 5 of 5, both hard ones: GPT-6 Astra, GPT-6 Luna and DeepSeek V4 Pro. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 writing prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 writing prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 19 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our writing test runs, model by model
How each model did on our 5 writing prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 3 of 5 | 0 of 2 | 1 each, of 31 a month on Pro | $0.0172 | 6.7 s |
| Claude Opus 5.5Anthropic | 4 of 5 | 1 of 2 | 1 each, of 62 a month on Pro | $0.0185 | 9.7 s |
| Claude Sonnet 5.5Anthropic | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0034 | 2.8 s |
| Claude Sonnet 5Anthropic | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0034 | 4.2 s |
| Claude Haiku 5.5Anthropic | 3 of 5 | 1 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 2.2 s |
| Claude Haiku 4.5Anthropic | 4 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0011 | 2.4 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0111 | 4.9 s |
| GPT-6.1 SolOpenAI | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0011 | 3.2 s |
| GPT-6 SolOpenAI | 4 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0023 | 3.1 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 2.1 s |
| Gemini 3.1 Pro (preview)Google | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0092 | 8.6 s |
| Gemini 3.8 FlashGoogle | 3 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0013 | 4.7 s |
| DeepSeek V4.1 FlashDeepSeek | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0005 | 1.6 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0011 | 3.8 s |
| Grok 4.7xAI | 3 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0058 | 9.4 s |
| Kimi K3Moonshot | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0038 | 2.9 s |
| GLM 5.3Z.ai | 4 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0006 | 1.7 s |
| GLM 5.3 FlashZ.ai | 2 of 5 | 0 of 2 | 1 each, of 60 a day on Pro | $0.0003 | 13.9 s |
| Mistral Large 4Mistral | 4 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0024 | 19.7 s |
One prompt, side by side
Each model's reply to “A product announcement with five rules”, as it came, with whether it passed and what it cost.
The prompt: A product announcement with five rules (hard)
Write a product announcement for the Nordvik 2 desk lamp in under 120 words. Include all five facts: it dims in five steps; it charges from USB-C; its arm turns 270 degrees; it costs €79; it ships on 1 December. Use no exclamation marks, and end with a question.
GPT-6 Astra
Passed: Graded 4.3 of 5 on average (lowest 4).
Meet the Nordvik 2, a desk lamp that puts light where you need it. Choose from five dimming steps, turn the arm 270 degrees to find your angle, and charge it via USB-C.

Priced at €79 and shipping on 1 December, the Nordvik 2 is ready for your next chapter, sketch or late-night idea.

Ready to see your desk in a new light?
406 tokens in, 87 out · 3.3 s · $0.0084 · 1 message on Pro · answered by openai/gpt-6-astra via OpenAI ·
DeepSeek V4 Pro
Passed: Graded 4.3 of 5 on average (lowest 4).
Introducing the Nordvik 2 desk lamp. It dims in five steps, so you can find the right light for any task. It charges over USB-C, keeping your desk free of extra cables. The arm turns 270 degrees for precise positioning. Available for €79, with shipping on 1 December. Have you reserved yours yet?
418 tokens in, 96 out (25 of them reasoning) · 1.8 s · $0.0005 · 1 message on Pro · answered by deepseek/deepseek-v4-pro-0813 via Wafer ·
GPT-6 Luna
Passed: Graded 4.0 of 5 on average (lowest 3).
Meet the Nordvik 2, a desk lamp designed to bring flexible light to your workspace. Choose from five brightness levels, charge it via USB-C, and turn its arm up to 270 degrees to direct light where you need it. The Nordvik 2 costs €79 and ships on 1 December. Ready to brighten your desk?
406 tokens in, 73 out · 1.5 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
The writing prompts, and how they're scored
Rubric (graded). The grader model scores the reply from 1 to 5 on each published criterion. It passes with an average of 4 or more and no criterion under 3, and only if it also meets the prompt's automatic rules (length, words it must or mustn't use).
The grader is Claude Opus 5.5 at low reasoning effort; its own replies are graded by GPT-6 Astra, so no model grades itself. Its prompt and every rubric are on the methods page.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five writing prompts and how every reply was scored.
Prompts like these to try yourself
What matters for writing
Voice and tone
The best draft is the one that sounds like you. Models differ in how well they pick up a voice from examples.
Following the brief
Word counts, audiences, must-include points: a good writing model keeps to the brief.
Editing, not just drafting
Most writing is editing. Ask for changes to a draft rather than a new one each time.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | 1 message | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | Yes | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | Yes | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Writing in llmwise
Drafts as documents
Drafts open as documents beside the chat: edit them, step through versions and download them as PDF, Word or Markdown.
Personas
Pick the Writer persona, or make your own with your voice and a default model.
Web search with sources
The model can search the web and cite what it found as source cards, or read a link you paste. On Free, web search works inside your 5 trial messages; on a paid plan a search counts as one more message of the model in use.
Switch models mid-chat
Start on a cheaper model; if the answer isn't good enough, switch models in the same chat. The next model sees the whole conversation, so you don't paste anything twice.
Tips
Say who it's for, how long, and what it must include.
Paste a paragraph you like and ask for that voice.
Ask for three options for headlines and openings.
Get a second opinion: switch models and ask for a critique of the draft.
Questions
What is the best AI for writing?
In our test runs on October 9, 2026, 3 of the 19 models passed 5 of 5 writing prompts, so these prompts don't name one best model. For best value, DeepSeek V4 Pro (5 of 5). For everyday, GPT-6 Luna (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for writing?
We sent the same writing prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for writing for free?
Yes, to try: Free is a one-time trial of 5 messages on every model but Claude Fable 5.1 and GPT-6 Astra (one of them can be on Claude Opus 5.5).
Can I export what it writes?
Yes. Ask for a document and it downloads as PDF, Word or Markdown, with every version kept.
Can it write in my style?
Give it a few samples of your writing and describe your style, or save both in a persona so every chat starts with them.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.