Comparison · Coding
ChatGPT vs Grok for coding
On llmwise Pro, GPT-6.1 Sol gets up to 125 messages a month and Grok 4.7 up to 250 messages a month. ChatGPT is OpenAI's own app for its GPT models; llmwise has GPT models in its own chat, not ChatGPT itself. We ran the same 5 coding prompts on all 4 GPT models and Grok's one model and published every reply: the results, then GPT-6 Luna against Grok 4.7 prompt by prompt, then how GPT and Grok compare on price per message, context and files.
Based on 25 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
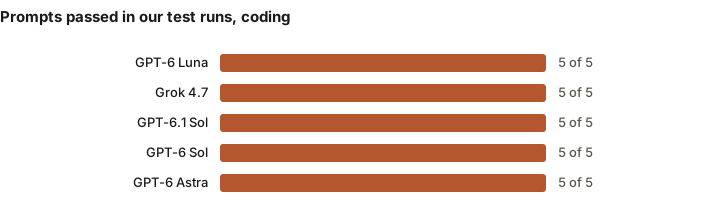
In our coding test runs on October 2, 2026, GPT's 4 models passed 20 of 20; GPT-6 Astra, GPT-6.1 Sol and 2 more each passed 5 of 5. Grok's one model passed 5 of 5 ($0.0246 a reply). GPT-6 Luna and Grok 4.7 each passed 5 of the 5 prompts, so these coding prompts don't split GPT and Grok; the replies on this page show how they differ.
GPT and Grok on our coding test runs
Every GPT and Grok model in llmwise on our 5 coding prompts: how many replies passed, what each counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0223 | 6.8 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0023 | 4.9 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0052 | 5.7 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0003 | 4.9 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0246 | 46.9 s |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
GPT vs Grok, prompt by prompt
Each coding prompt with GPT-6 Luna and Grok 4.7 side by side, as they replied: for each side, the model that passed the most coding prompts (then the most hard ones, then the cheaper).
Coding: GPT-6 Luna passed 5 of 5 and Grok 4.7 5 of 5. GPT-6 Luna answered 6.9× sooner at the median, 4.6 s against 31.6 s. GPT-6 Luna cost 85.8× less, $0.0014 against $0.1229 for the 5 replies. Grok 4.7's replies ran 21% longer, in tokens of reply, thinking not counted.
1. Turn a title into a URL slug
Everyday. GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001 · Grok: 1 of 1 model passed, Grok 4.7 at $0.0078. The prompt in full.
GPT-6 Luna and Grok 4.7 both passed this one. GPT-6 Luna answered sooner (2.3 s to 14.3 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0078); GPT-6 Luna wrote 74 tokens of reply, Grok 4.7 73.
GPT-6 Luna
Passed: All 7 tests passed.
```javascript
function slugify(title) {
  return title
    .toLowerCase()
    .normalize("NFD")
    .replace(/[\u0300-\u036f]/g, "")
    .replace(/[^a-z0-9]+/g, "-")
    .replace(/^-|-$/g, "");
}
```
483 tokens in, 74 out · 2.3 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Grok 4.7
Passed: All 7 tests passed.
```javascript
function slugify(title) {
  return title
    .normalize("NFD")
    .replace(/\p{M}/gu, "")
    .toLowerCase()
    .replace(/[^a-z0-9]+/g, "-")
    .replace(/^-+|-+$/g, "");
}
```
1,720 tokens in, 1,012 out (939 of them reasoning) · 14.3 s · $0.0078 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
2. Parse a duration like “1h 30m”
Everyday. GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0003 · Grok: 1 of 1 model passed, Grok 4.7 at $0.0167. The prompt in full.
GPT-6 Luna and Grok 4.7 both passed this one. GPT-6 Luna answered sooner (4.6 s to 31.6 s), and GPT-6 Luna's reply cost less ($0.0003 to $0.0167); GPT-6 Luna wrote 138 tokens of reply, Grok 4.7 171.
GPT-6 Luna
Passed: All 10 tests passed.
```javascript
function parseDuration(text) {
  if (typeof text !== "string") return null;

  const match = text.match(/^\s*(?:(\d+)h)?\s*(?:(\d+)m)?\s*(?:(\d+)s)?\s*$/);
  if (!match || !match[1] && !match[2] && !match[3]) return null;

  return Number(match[1] || 0) * 3600
    + Number(match[2] || 0) * 60
    + Number(match[3] || 0);
}
```
468 tokens in, 407 out (269 of them reasoning) · 4.6 s · $0.0003 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Grok 4.7
Passed: All 10 tests passed.
```javascript
function parseDuration(text) {
  if (typeof text !== "string") return null;
  const match = text.match(/^\s*(?:(\d+)h)?\s*(?:(\d+)m)?\s*(?:(\d+)s)?\s*$/);
  if (!match || (match[1] == null && match[2] == null && match[3] == null)) return null;
  const hours = match[1] != null ? Number(match[1]) : 0;
  const minutes = match[2] != null ? Number(match[2]) : 0;
  const seconds = match[3] != null ? Number(match[3]) : 0;
  return hours * 3600 + minutes * 60 + seconds;
}
```
1,706 tokens in, 2,497 out (2,326 of them reasoning) · 31.6 s · $0.0167 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
3. Merge overlapping intervals
Everyday. GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001 · Grok: 1 of 1 model passed, Grok 4.7 at $0.0045. The prompt in full.
GPT-6 Luna and Grok 4.7 both passed this one. GPT-6 Luna answered sooner (1.5 s to 6.1 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0045); GPT-6 Luna wrote 130 tokens of reply, Grok 4.7 198.
GPT-6 Luna
Passed: All 7 tests passed.
```javascript
function mergeIntervals(intervals) {
  const sorted = intervals
    .map(([start, end]) => [start, end])
    .sort((a, b) => a[0] - b[0]);

  const merged = [];

  for (const [start, end] of sorted) {
    const last = merged[merged.length - 1];

    if (!last || start > last[1]) {
      merged.push([start, end]);
    } else {
      last[1] = Math.max(last[1], end);
    }
  }

  return merged;
}
```
449 tokens in, 130 out · 1.5 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Grok 4.7
Passed: All 7 tests passed.
```javascript
function mergeIntervals(intervals) {
  if (!intervals || intervals.length === 0) return [];

  const sorted = intervals
    .map((iv) => [iv[0], iv[1]])
    .sort((a, b) => a[0] - b[0] || a[1] - b[1]);

  const merged = [[sorted[0][0], sorted[0][1]]];

  for (let i = 1; i < sorted.length; i++) {
    const last = merged[merged.length - 1];
    const curr = sorted[i];
    if (curr[0] <= last[1]) {
      if (curr[1] > last[1]) last[1] = curr[1];
    } else {
      merged.push([curr[0], curr[1]]);
    }
  }

  return merged;
}
```
1,684 tokens in, 547 out (349 of them reasoning) · 6.1 s · $0.0045 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
4. Evaluate an arithmetic expression, no eval
Hard. GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0006 · Grok: 1 of 1 model passed, Grok 4.7 at $0.0574. The prompt in full.
GPT-6 Luna and Grok 4.7 both passed this one. GPT-6 Luna answered sooner (8.8 s to 110.1 s), and GPT-6 Luna's reply cost less ($0.0006 to $0.0574); GPT-6 Luna wrote 552 tokens of reply, Grok 4.7 613.
GPT-6 Luna
Passed: All 15 tests passed.
```javascript
function evaluate(expression) {
  if (typeof expression !== "string") {
    throw new Error("Expression must be a string");
  }

  let index = 0;

  function skipSpaces() {
    while (index < expression.length && /\s/.test(expression[index])) {
      index++;
    }
  }

  function parsePrimary() {
    skipSpaces();

    if (expression[index] === "(") {
      index++;
      const value = parseExpression();
      skipSpaces();
      if (expression[index] !== ")") throw new Error("Missing closing parenthesis");
      index++;
      return value;
    }

    const start = index;
    let digitsBefore = 0;
    while (/\d/.test(expression[index] || "")) {
      index++;
      digitsBefore++;
    }

    let digitsAfter = 0;
    if (expression[index] === ".") {
      index++;
      while (/\d/.test(expression[index] || "")) {
        index++;
        digitsAfter++;
      }
    }

    if (digitsBefore === 0 && digitsAfter === 0) {
      throw new Error("Expected a number or parenthesized expression");
    }

    return Number(expression.slice(start, index));
  }

  // Unary minus has lower precedence than exponentiation, but is allowed
  // on an exponent's right-hand side.
  function parseUnary() {
    skipSpaces();
    if (expression[index] === "-") {
      index++;
      return -parseUnary();
    }
    return parsePower();
  }

  function parsePower() {
    let value = parsePrimary();
    skipSpaces();

    if (expression[index] === "^") {
      index++;
      value **= parseUnary();
    }

    return value;
  }

  function parseProduct() {
    let value = parseUnary();

    while (true) {
      skipSpaces();
      const operator = expression[index];
      if (operator !== "*" && operator !== "/") break;

      index++;
      const right = parseUnary();
      value = operator === "*" ? value * right : value / right;
    }

    return value;
  }

  function parseExpression() {
    let value = parseProduct();

    while (true) {
      skipSpaces();
      const operator = expression[index];
      if (operator !== "+" && operator !== "-") break;

      index++;
      const right = parseProduct();
      value = operator === "+" ? value + right : value - right;
    }

    return value;
  }

  const result = parseExpression();
  skipSpaces();
  if (index !== expression.length) throw new Error("Unexpected input");

  return result;
}
```
549 tokens in, 1,007 out (455 of them reasoning) · 8.8 s · $0.0006 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Grok 4.7
Passed: All 15 tests passed.
```javascript
function evaluate(expression) {
  if (typeof expression !== 'string') {
    throw new Error('Invalid expression');
  }

  const s = expression;
  let i = 0;

  function skip() {
    while (i < s.length && s[i] === ' ') i++;
  }

  function parseExpression() {
    let value = parseTerm();
    while (true) {
      skip();
      if (s[i] === '+') {
        i++;
        value += parseTerm();
      } else if (s[i] === '-') {
        i++;
        value -= parseTerm();
      } else {
        break;
      }
    }
    return value;
  }

  function parseTerm() {
    let value = parseUnary();
    while (true) {
      skip();
      if (s[i] === '*') {
        i++;
        value *= parseUnary();
      } else if (s[i] === '/') {
        i++;
        value /= parseUnary();
      } else {
        break;
      }
    }
    return value;
  }

  function parseUnary() {
    skip();
    if (s[i] === '-') {
      i++;
      return -parseUnary();
    }
    return parsePower();
  }

  function parsePower() {
    const base = parsePrimary();
    skip();
    if (s[i] === '^') {
      i++;
      return base ** parseUnary();
    }
    return base;
  }

  function parsePrimary() {
    skip();
    if (s[i] === '(') {
      i++;
      const value = parseExpression();
      skip();
      if (s[i] !== ')') throw new Error('Invalid expression');
      i++;
      return value;
    }
    return parseNumber();
  }

  function parseNumber() {
    skip();
    const start = i;
    if (i >= s.length || s[i] < '0' || s[i] > '9') {
      throw new Error('Invalid expression');
    }
    while (i < s.length && s[i] >= '0' && s[i] <= '9') i++;
    if (s[i] === '.') {
      i++;
      if (i >= s.length || s[i] < '0' || s[i] > '9') {
        throw new Error('Invalid expression');
      }
      while (i < s.length && s[i] >= '0' && s[i] <= '9') i++;
    }
    return Number(s.slice(start, i));
  }

  const value = parseExpression();
  skip();
  if (i !== s.length) throw new Error('Invalid expression');
  return value;
}
```
1,786 tokens in, 9,267 out (8,654 of them reasoning) · 110.1 s · $0.0574 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
5. Parse CSV with quoted fields
Hard. GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0004 · Grok: 1 of 1 model passed, Grok 4.7 at $0.0364. The prompt in full.
GPT-6 Luna and Grok 4.7 both passed this one. GPT-6 Luna answered sooner (7.2 s to 72.2 s), and GPT-6 Luna's reply cost less ($0.0004 to $0.0364); GPT-6 Luna wrote 315 tokens of reply, Grok 4.7 402.
GPT-6 Luna
Passed: All 8 tests passed.
```javascript
function parseCsv(text) {
  if (text === "") return [];

  const rows = [];
  let row = [];
  let field = "";
  let inQuotes = false;
  let endedWithRowBreak = false;

  for (let i = 0; i < text.length; i++) {
    const char = text[i];

    if (inQuotes) {
      if (char === '"') {
        if (text[i + 1] === '"') {
          field += '"';
          i++;
        } else {
          inQuotes = false;
        }
      } else {
        field += char;
      }
      endedWithRowBreak = false;
      continue;
    }

    if (char === '"' && field === "") {
      inQuotes = true;
      endedWithRowBreak = false;
    } else if (char === ",") {
      row.push(field);
      field = "";
      endedWithRowBreak = false;
    } else if (char === "\n" || (char === "\r" && text[i + 1] === "\n")) {
      row.push(field);
      rows.push(row);
      row = [];
      field = "";
      if (char === "\r") i++;
      endedWithRowBreak = true;
    } else {
      field += char;
      endedWithRowBreak = false;
    }
  }

  if (!endedWithRowBreak) {
    row.push(field);
    rows.push(row);
  }

  return rows;
}
```
481 tokens in, 762 out (447 of them reasoning) · 7.2 s · $0.0004 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Grok 4.7
Passed: All 8 tests passed.
```javascript
function parseCsv(text) {
  if (text === "") return [];

  const rows = [];
  let row = [];
  let field = "";
  let inQuotes = false;
  let atFieldStart = true;
  let endedOnBreak = false;

  for (let i = 0; i < text.length; ) {
    const c = text[i];

    if (inQuotes) {
      if (c === '"') {
        if (text[i + 1] === '"') {
          field += '"';
          i += 2;
        } else {
          inQuotes = false;
          i += 1;
        }
      } else {
        field += c;
        i += 1;
      }
      endedOnBreak = false;
      continue;
    }

    if (atFieldStart && c === '"') {
      inQuotes = true;
      atFieldStart = false;
      endedOnBreak = false;
      i += 1;
      continue;
    }

    if (c === ",") {
      row.push(field);
      field = "";
      atFieldStart = true;
      endedOnBreak = false;
      i += 1;
      continue;
    }

    if (c === "\n" || (c === "\r" && text[i + 1] === "\n")) {
      row.push(field);
      rows.push(row);
      row = [];
      field = "";
      atFieldStart = true;
      endedOnBreak = true;
      i += c === "\r" ? 2 : 1;
      continue;
    }

    field += c;
    atFieldStart = false;
    endedOnBreak = false;
    i += 1;
  }

  if (!endedOnBreak) {
    row.push(field);
    rows.push(row);
  }

  return rows;
}
```
1,718 tokens in, 5,854 out (5,452 of them reasoning) · 72.2 s · $0.0364 · 1 message on Pro · answered by x-ai/grok-4.7 via xAI ·
Each GPT model against each Grok model
Every GPT model against every Grok model on the same 5 coding prompts: passes, the median wait and what the replies cost. A lead under 10% counts as close.
GPT-6 Astra vs Grok 4.7: 5 of 5 each; GPT-6 Astra answered 3.9× sooner at the median and cost 1.1× less. GPT-6 Astra vs Grok 4.7, on every job.
GPT-6.1 Sol vs Grok 4.7: 5 of 5 each; GPT-6.1 Sol answered 6.6× sooner at the median and cost 10.7× less.
GPT-6 Sol vs Grok 4.7: 5 of 5 each; GPT-6 Sol answered 6.6× sooner at the median and cost 4.7× less. GPT-6 Sol vs Grok 4.7, on every job.
GPT-6 Luna vs Grok 4.7: 5 of 5 each; GPT-6 Luna answered 6.9× sooner at the median and cost 85.8× less. GPT-6 Luna vs Grok 4.7, on every job.
How the coding replies are scored
Every GPT and Grok reply above was checked the same way as every other model's, by the rules published with the prompts: how the coding prompts are scored, and each one in full.
The differences at a glance
What follows from each model's facts in our catalog.
The lineups
GPT: 4 models, GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, and GPT-6 Luna. Grok: one model, Grok 4.7.
Price per message
The least expensive GPT model is GPT-6 Luna (60 messages a day on Pro); Grok's one model is Grok 4.7 (250 messages a month on Pro).
Context window
GPT goes up to 1.05M tokens (GPT-6 Astra); Grok up to 500K tokens (Grok 4.7).
Images and PDFs
Every model here reads images. Every model here takes a PDF as a whole file.
On the Free plan
Free's one-time trial of 5 messages covers GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna, and Grok 4.7. Paid plans have every model, with messages every month.
Every GPT and Grok model's context window, files and API price: Grok vs ChatGPT.
Where your messages go
In llmwise, a message to GPT goes to its maker, OpenAI, or through OpenRouter when llmwise can't reach the maker directly. Grok models are served only through OpenRouter, by endpoints that don't store or train on prompts. The Privacy Policy has the details.
Questions
Which is better, ChatGPT or Grok for coding?
In our coding test runs on October 2, 2026, GPT's 4 models passed 20 of 20; GPT-6 Astra, GPT-6.1 Sol and 2 more each passed 5 of 5. Grok's one model passed 5 of 5 ($0.0246 a reply). GPT-6 Luna and Grok 4.7 each passed 5 of the 5 prompts, so these coding prompts don't split GPT and Grok; the replies on this page show how they differ.
Is GPT or Grok cheaper?
In llmwise, the least expensive GPT model is GPT-6 Luna (60 messages a day on Pro), and the least expensive Grok model is Grok 4.7 (250 messages a month on Pro). At API list prices (October 2026), a typical message of 4,000 tokens in and 700 out costs $0.0008 on GPT-6 Luna and $0.0122 on Grok 4.7.
Can I use GPT and Grok in the same chat?
Yes. Ask GPT-6 Luna a question, then switch the picker to Grok 4.7 and ask again: Grok 4.7 sees the whole conversation, GPT-6 Luna's answer included.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.