Best AI · Math
The best AI for math
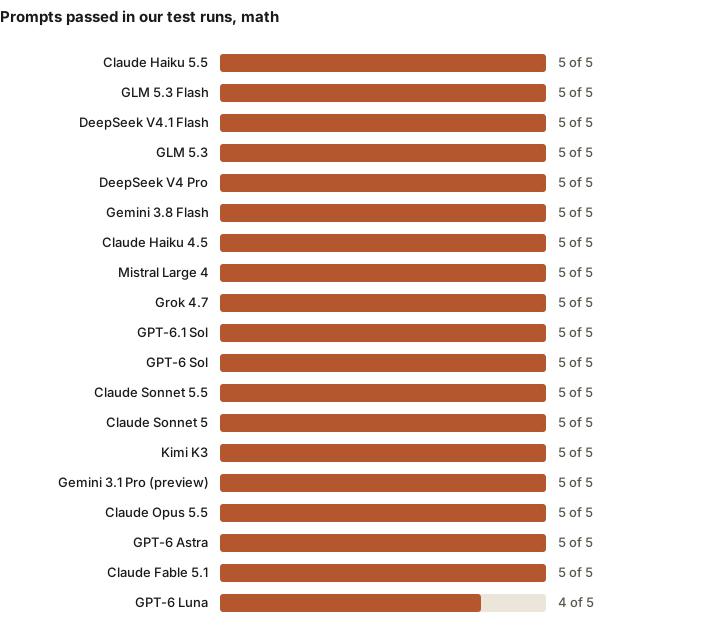
In our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026, 18 of the 19 models passed 5 of 5 math prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). Our picks below follow fixed rules, beside each model's price per message, and every prompt and reply is published.
Based on 95 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
In our test runs on October 9, 2026, 18 models passed 5 of 5 math prompts, so these prompts don't pick one for hard problems. For value, GLM 5.3 (5 of 5), 250 a month on Pro; for everyday math, Claude Haiku 5.5 (5 of 5), from the daily count.
Our picks for math
Hard problems
Shared by 18 models
18 models passed 5 of 5, both hard ones: Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5 and 15 more. These prompts don't tell them apart, so they share the pick.
Best value
Passed 5 of 5 math prompts, with 250 a month on Pro.
Everyday
Passed 5 of 5 math prompts; an everyday model, so its messages come from the daily count (60 a day on Pro), not the monthly allowance.
These picks aren't our opinion: they're what the results below give, by these rules, among all 19 models in llmwise. They change when the results do.
- Hard problems: the model that passed the most prompts and, of those, the most hard ones. Models level on both share the pick: the prompts don't tell them apart, so we don't break the tie by price or by name.
- Best value: among the models that draw on the monthly allowance, the one with the most messages on Pro that passed no more than one prompt fewer than the top model. Ties go to the one that passed more, then to the lower cost per reply.
- Everyday: among the cheapest models on the page (the everyday models, which come from the daily count, when the page has any), the one that passed the most. Ties go to the one that passed more of the hard prompts, then to the lower cost per reply.
Our math test runs, model by model
How each model did on our 5 math prompts, what each reply counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0116 | 4.6 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0060 | 4.1 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0025 | 1.7 s |
| Claude Sonnet 5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0033 | 4.1 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 1.7 s |
| Claude Haiku 4.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0015 | 2.4 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0085 | 2.7 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0009 | 2.0 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0018 | 2.2 s |
| GPT-6 LunaOpenAI | 4 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0001 | 2.4 s |
| Gemini 3.1 Pro (preview)Google | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0100 | 7.5 s |
| Gemini 3.8 FlashGoogle | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0014 | 3.8 s |
| DeepSeek V4.1 FlashDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 1.1 s |
| DeepSeek V4 ProDeepSeek | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0009 | 2.9 s |
| Grok 4.7xAI | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0072 | 11.6 s |
| Kimi K3Moonshot | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0037 | 4.9 s |
| GLM 5.3Z.ai | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0004 | 1.1 s |
| GLM 5.3 FlashZ.ai | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 5.1 s |
| Mistral Large 4Mistral | 5 of 5 | 2 of 2 | 1 each, of 250 a month on Pro | $0.0018 | 10.2 s |
One prompt, side by side
Each model's reply to “Four-digit numbers whose digits sum to 9”, as it came, with whether it passed and what it cost.
The prompt: Four-digit numbers whose digits sum to 9 (hard)
How many four-digit positive integers have digits that add up to 9?
Show your working briefly, then end with a line that says "Final answer: " followed by the answer alone.
Claude Fable 5.1
Passed: Final answer 165: right.
Let the digits be a, b, c, d with a ≥ 1 (leading digit) and b, c, d ≥ 0, and a + b + c + d = 9.

Substitute a' = a − 1 ≥ 0, so a' + b + c + d = 8 with all variables ≥ 0.

Number of non-negative integer solutions: C(8 + 3, 3) = C(11, 3) = 165.

No digit can exceed 9 since the total is only 9, so no solutions need to be excluded.

Final answer: 165
512 tokens in, 175 out · 4.6 s · $0.0139 · 1 message on Pro · answered by anthropic/claude-fable-5.1 via Anthropic ·
GLM 5.3
Passed: Final answer 165: right.
# Working

We need four-digit numbers (1000–9999) with digit sum 9.

Let the digits be $a, b, c, d$ where $a \in \{1,\dots,9\}$ and $b,c,d \in \{0,\dots,9\}$, with $a+b+c+d=9$.

Set $a' = a-1 \geq 0$, so $a'+b+c+d = 8$ with each variable $\leq 9$ (automatically satisfied since sum is 8).

Stars and bars: $\binom{8+3}{3} = \binom{11}{3} = 165$.

Final answer: 165
392 tokens in, 154 out · 1.9 s · $0.0003 · 1 message on Pro · answered by z-ai/glm-5.3 via Baidu ·
Claude Haiku 5.5
Passed: Final answer 165: right.
We need four-digit numbers d1 d2 d3 d4 with d1 from 1 to 9, d2, d3, d4 from 0 to 9, and digit sum 9.

Substitute e1 = d1 − 1, so e1 ranges 0 to 8, and e1 + d2 + d3 + d4 = 8 with all variables from 0 to 9.

Since the sum is 8, no variable can exceed 8, so the upper bound of 9 is never violated. The number of nonnegative solutions is C(8+3, 3) = C(11, 3) = 165.

Check: total solutions with d1 ≥ 0 allowed (i.e., first digit could be 0) for sum 9 across four digits is C(12, 3) = 220. Those with d1 = 0 correspond to three digits summing to 9: C(11, 2) = 55. So 220 − 55 = 165, which matches.

Final answer: 165
513 tokens in, 305 out · 1.9 s · $0.0002 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
The math prompts, and how they're scored
Final answer. Automatic. The reply's last “Final answer:” line must hold the right value.
Each prompt was sent the way llmwise sends a message in a side-by-side comparison, which offers no tools: the app's own system prompt, the model's own settings, and Pro's reply size limit (8,000 tokens). Read all five math prompts and how every reply was scored.
Prompts like these to try yourself
What matters for math
Step-by-step reasoning
Models that reason before answering work through the steps instead of jumping to a number, which matters most on multi-step problems.
Checking the arithmetic
Language models can slip on arithmetic. Running the calculation as code settles it.
Showing the work
A good answer shows its steps clearly enough for you to follow, and flags its assumptions.
Every model at a glance
| Model | On Pro | On Free | Context window | Images | PDFs | Reasoning | API price per 1M, in / out |
|---|---|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 31/mo on Pro | No | 1M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| Claude Opus 5.5Anthropic | 62/mo on Pro | 1 message | 1M tokens | Yes | Whole file | Yes | $4.00 / $20.00 |
| Claude Sonnet 5.5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Sonnet 5Anthropic | 125/mo on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| Claude Haiku 5.5Anthropic | 60/day on Pro | Yes | 1M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Claude Haiku 4.5Anthropic | 250/mo on Pro | Yes | 200K tokens | Yes | Whole file | No | $1.00 / $5.00 |
| GPT-6 AstraOpenAI | 31/mo on Pro | No | 1.05M tokens | Yes | Whole file | Yes | $10.00 / $50.00 |
| GPT-6.1 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 SolOpenAI | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $10.00 |
| GPT-6 LunaOpenAI | 60/day on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.10 / $0.50 |
| Gemini 3.1 Pro (preview)Google | 125/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $2.00 / $12.00 |
| Gemini 3.8 FlashGoogle | 250/mo on Pro | Yes | 1.05M tokens | Yes | Whole file | Yes | $0.75 / $3.75 |
| DeepSeek V4.1 FlashDeepSeek | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.30 / $1.20 |
| DeepSeek V4 ProDeepSeek | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $0.40 / $4.00 |
| Grok 4.7xAI | 250/mo on Pro | Yes | 500K tokens | Yes | Whole file | Yes | $2.00 / $6.00 |
| Kimi K3Moonshot | 125/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $3.00 / $15.00 |
| GLM 5.3Z.ai | 250/mo on Pro | Yes | 1.05M tokens | No | Text only | Yes | $1.40 / $4.40 |
| GLM 5.3 FlashZ.ai | 60/day on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.15 / $0.50 |
| Mistral Large 4Mistral | 250/mo on Pro | Yes | 1.05M tokens | Yes | Text only | Yes | $0.68 / $2.09 |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Math in llmwise
Readable formulas
Formulas in answers render as proper math, not raw LaTeX.
Run code (paid plans)
On a paid plan the model can run Python or Node.js in an isolated sandbox once you approve it, read the output and fix what failed. A run counts as 1 Claude Haiku 4.5 message and stops after 60 seconds.
Photos of problems
Attach a photo of a worksheet or a screenshot of a problem to a model that reads images.
The Tutor persona
Pick the Tutor persona to have concepts explained step by step, with checks that you followed.
Tips
Ask for the steps, not just the answer.
Say what level you're at, so the explanation fits.
Ask the model to verify the final answer a second way.
For proofs, ask it to list its assumptions.
Questions
What is the best AI for math?
In our test runs on October 9, 2026, 18 of the 19 models passed 5 of 5 math prompts, so these prompts don't name one best model. For best value, GLM 5.3 (5 of 5). For everyday, Claude Haiku 5.5 (5 of 5). Every prompt and reply is published, so you can check them, and the picks follow fixed rules.
How did you test the models for math?
We sent the same math prompts to every model through llmwise's own pipeline and checked each reply the same way. The prompts, the replies, how each was scored and the grader are all published on the methods page.
Can I try these models for math for free?
Yes, to try: Free is a one-time trial of 5 messages on every model but Claude Fable 5.1 and GPT-6 Astra (one of them can be on Claude Opus 5.5).
Can it check its own answer?
On a paid plan, ask the model to check its answer with code: it runs Python in a sandbox (after you approve) and compares. A run counts as 1 Claude Haiku 4.5 message.
Can I send a photo of a problem?
Yes, to a model that reads images: attach the photo or screenshot. The table below shows which models do.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.