AI data
Updated · By llmwise, AI-assisted.
Price per task: what finishing an AI task costs, model by model
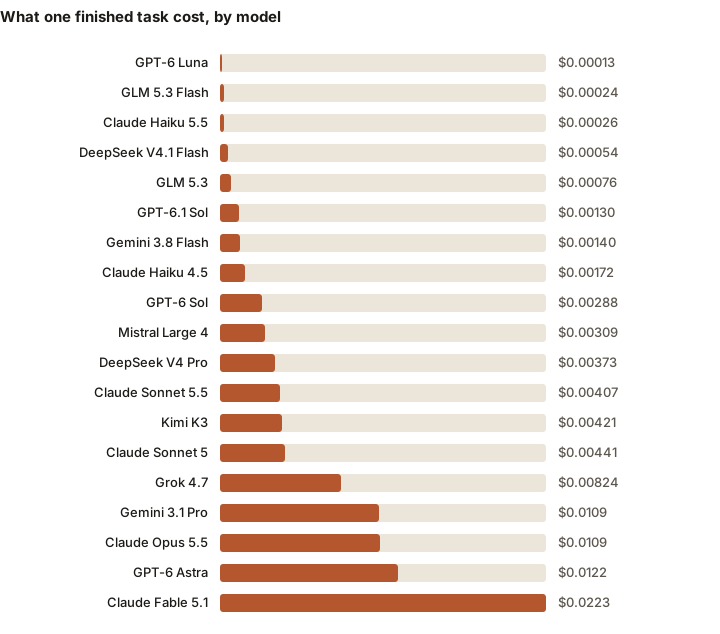
Finishing one task cost from $0.00013 on GPT-6 Luna to $0.0223 on Claude Fable 5.1, 177 times as much, in our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026. A finished task is a reply that passed its check. Each figure is what OpenRouter charged for all 50 prompts, divided by how many passed.
The price per task index
Everything each model was charged for our 50 prompts, divided by the replies that passed their check, cheapest first. “Times the cheapest” is against GPT-6 Luna.
| Model | Tasks passed | Price per task | Times the cheapest | Spent on all |
|---|---|---|---|---|
| GPT-6 Luna | 47 of 50 | $0.00013 | the cheapest | $0.0059 |
| GLM 5.3 Flash | 40 of 50 | $0.00024 | 1.9 times | $0.0096 |
| Claude Haiku 5.5 | 45 of 50 | $0.00026 | 2.1 times | $0.0118 |
| DeepSeek V4.1 Flash | 48 of 50 | $0.00054 | 4.3 times | $0.0260 |
| GLM 5.3 | 48 of 50 | $0.00076 | 6 times | $0.0364 |
| GPT-6.1 Sol | 46 of 50 | $0.0013 | 10 times | $0.0597 |
| Gemini 3.8 Flash | 46 of 50 | $0.0014 | 11 times | $0.0644 |
| Claude Haiku 4.5 | 43 of 50 | $0.0017 | 14 times | $0.0741 |
| GPT-6 Sol | 45 of 50 | $0.0029 | 23 times | $0.1297 |
| Mistral Large 4 | 47 of 50 | $0.0031 | 25 times | $0.1453 |
| DeepSeek V4 Pro | 49 of 50 | $0.0037 | 30 times | $0.1827 |
| Claude Sonnet 5.5 | 47 of 50 | $0.0041 | 32 times | $0.1912 |
| Kimi K3 | 46 of 50 | $0.0042 | 34 times | $0.1938 |
| Claude Sonnet 5 | 46 of 50 | $0.0044 | 35 times | $0.2030 |
| Grok 4.7 | 47 of 50 | $0.0082 | 66 times | $0.3875 |
| Gemini 3.1 Pro | 49 of 50 | $0.0109 | 87 times | $0.5334 |
| Claude Opus 5.5 | 49 of 50 | $0.0109 | 87 times | $0.5360 |
| GPT-6 Astra | 48 of 50 | $0.0122 | 97 times | $0.5847 |
| Claude Fable 5.1 | 45 of 50 | $0.0223 | 177 times | $1.0018 |
The cheapest way to finish each job
Each job's five prompts on their own: the model that passed all five for the least per task, and the one that cost the most doing it.
| Job | Passed all five | Cheapest per task | Dearest per task |
|---|---|---|---|
| Coding | 17 of 19 models | GLM 5.3 Flash, $0.00025 | Claude Fable 5.1, $0.0425 |
| Writing | 3 of 19 models | GPT-6 Luna, $0.000099 | GPT-6 Astra, $0.0111 |
| Math | 18 of 19 models | Claude Haiku 5.5, $0.00015 | Claude Fable 5.1, $0.0116 |
| Summarization | 10 of 19 models | DeepSeek V4.1 Flash, $0.00020 | GPT-6 Astra, $0.0109 |
| Data analysis | 15 of 19 models | GPT-6 Luna, $0.00018 | Claude Fable 5.1, $0.0283 |
| Customer support | 4 of 19 models | GLM 5.3, $0.00047 | Claude Opus 5.5, $0.0108 |
| Translation | 18 of 19 models | GPT-6 Luna, $0.000093 | Claude Fable 5.1, $0.0175 |
| SQL | 19 of 19 models | GPT-6 Luna, $0.000089 | Claude Fable 5.1, $0.0185 |
| RAG and answering from documents | 19 of 19 models | GPT-6 Luna, $0.000077 | Claude Fable 5.1, $0.0145 |
| Agents and tool use | 18 of 19 models | GPT-6 Luna, $0.000081 | Claude Fable 5.1, $0.0119 |
Every model, every job
Every model's price per task on every job; a dash means none of its replies to that job passed.
| Model | Coding | Writing | Math | Summarization | Data analysis | Customer support | Translation | SQL | RAG and answering from documents | Agents and tool use |
|---|---|---|---|---|---|---|---|---|---|---|
| GPT-6 Luna | $0.00029 | $0.000099 | $0.00012 | $0.00012 | $0.00018 | $0.00011 | $0.000093 | $0.000089 | $0.000077 | $0.000081 |
| GLM 5.3 Flash | $0.00025 | $0.00080 | $0.00015 | $0.00019 | $0.00048 | $0.00049 | $0.000099 | $0.00013 | $0.00015 | $0.00016 |
| Claude Haiku 5.5 | $0.00045 | $0.00027 | $0.00015 | $0.00053 | $0.00036 | $0.00029 | $0.00018 | $0.00022 | $0.00014 | $0.00014 |
| DeepSeek V4.1 Flash | $0.0018 | $0.00056 | $0.00025 | $0.00020 | $0.00085 | $0.00058 | $0.00058 | $0.00020 | $0.00017 | $0.00020 |
| GLM 5.3 | $0.0015 | $0.00072 | $0.00035 | $0.00068 | $0.0019 | $0.00047 | $0.00070 | $0.00032 | $0.00050 | $0.00044 |
| GPT-6.1 Sol | $0.0023 | $0.0014 | $0.00086 | $0.0010 | $0.0016 | $0.0031 | $0.0013 | $0.00099 | $0.00079 | $0.00073 |
| Gemini 3.8 Flash | $0.0020 | $0.0022 | $0.0014 | $0.00075 | $0.0035 | $0.0020 | $0.00075 | $0.00074 | $0.00066 | $0.00087 |
| Claude Haiku 4.5 | $0.0046 | $0.0014 | $0.0015 | $0.0010 | $0.0042 | $0.0024 | $0.0015 | $0.00099 | $0.0010 | $0.00095 |
| GPT-6 Sol | $0.0052 | $0.0028 | $0.0018 | $0.0027 | $0.0034 | $0.0049 | $0.0035 | $0.0021 | $0.0016 | $0.0016 |
| Mistral Large 4 | $0.0091 | $0.0030 | $0.0018 | $0.0043 | $0.0037 | $0.0019 | $0.0031 | $0.0022 | $0.0014 | $0.0013 |
| DeepSeek V4 Pro | $0.0240 | $0.0011 | $0.00088 | $0.00091 | $0.0029 | $0.0019 | $0.0020 | $0.0020 | $0.00060 | $0.00066 |
| Claude Sonnet 5.5 | $0.0063 | $0.0043 | $0.0025 | $0.0042 | $0.0047 | $0.0058 | $0.0042 | $0.0038 | $0.0028 | $0.0026 |
| Kimi K3 | $0.0063 | $0.0048 | $0.0037 | $0.0057 | $0.0068 | $0.0057 | $0.0036 | $0.0024 | $0.0015 | $0.0027 |
| Claude Sonnet 5 | $0.0102 | $0.0043 | $0.0033 | $0.0047 | $0.0086 | $0.0036 | $0.0030 | $0.0028 | $0.0022 | $0.0024 |
| Grok 4.7 | $0.0246 | $0.0096 | $0.0072 | $0.0028 | $0.0111 | $0.0077 | $0.0082 | $0.0048 | $0.0029 | $0.0039 |
| Gemini 3.1 Pro | $0.0195 | $0.0115 | $0.0100 | $0.0088 | $0.0155 | $0.0106 | $0.0140 | $0.0077 | $0.0058 | $0.0057 |
| Claude Opus 5.5 | $0.0171 | $0.0231 | $0.0060 | $0.0095 | $0.0131 | $0.0108 | $0.0108 | $0.0092 | $0.0073 | $0.0050 |
| GPT-6 Astra | $0.0223 | $0.0111 | $0.0085 | $0.0109 | $0.0154 | $0.0193 | $0.0126 | $0.0098 | $0.0079 | $0.0068 |
| Claude Fable 5.1 | $0.0425 | $0.0287 | $0.0116 | $0.0268 | $0.0283 | $0.0276 | $0.0175 | $0.0185 | $0.0145 | $0.0119 |
In llmwise you pay per message instead, a count you see before you send: each model's price per message on every plan is on its page of what an AI message costs.
More AI data
- Messages per $20: every AI plan that publishes a count, and llmwise's
- AI price and limit changelog: every dated change, sourced
- Which AI plan gets the newest models? Plan by plan
- AI chat privacy scorecard: who trains on your chats, and for how long they keep them
- AI model quality tracker: the same prompts, every model, dated
- The AI model leaderboard, job by job
- Subscription stack calculator: what your AI plans cost together
- AI data studies: prices, limits, access and privacy
Also from primary sources: OpenRouter's usage accounting docs (the cost OpenRouter reports for every request, which these figures add up). Anthropic's Claude Opus 5.5 page (the model that grades the rubric prompts). OpenAI's GPT-6 Astra docs (the model that grades Claude Opus 5.5's own replies). Read .
Price per task: how it's worked out
How is the price per task worked out?
Everything OpenRouter charged for a model's replies to a job's prompts, passed or not, divided by the replies that passed their check. A model that fails often pays for its failures: its price per task rises with them.
Is this what llmwise charges?
No. In llmwise a message is one of your plan's published count, however long the reply runs, so a model's price per message on a plan doesn't move with its tokens. This study is what the same work costs through the models' APIs.
Will my own tasks cost the same?
Our prompts start new chats and ask for one reply each: a long chat or a long document costs more, since every reply rereads it. The runs count for 45 days; we run them again after that, and when a model's price changes.
Run your own task on the models that passed
Every model in these runs is in llmwise, its count shown before you send. Start on the cheapest one that passed, and switch up only when a task needs it.