AI data
Updated · By llmwise, AI-assisted.
AI model quality tracker: the same prompts, every model, dated
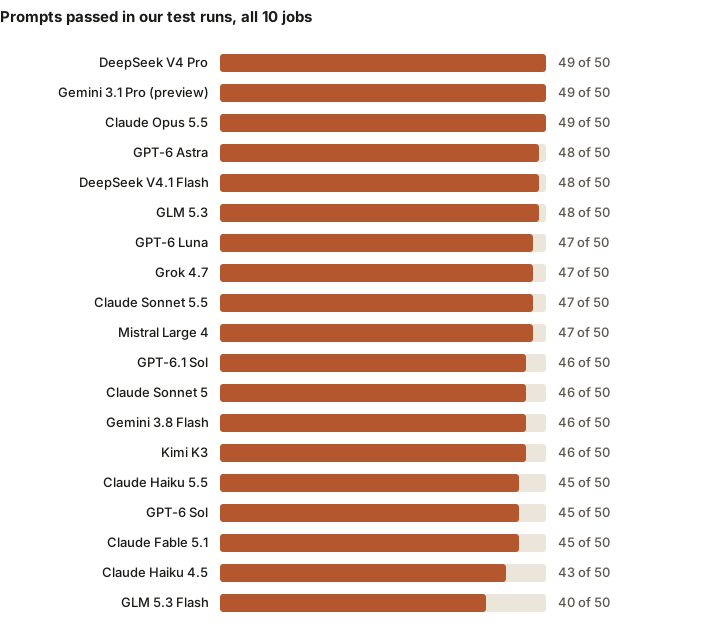
A dated snapshot, not a trend yet: all 20 models ran the same 50 prompts on September 27, 28, 29 and October 2, 7, 8, 9, 15, 2026. They passed from 40 (GLM 5.3 Flash) to 49 (DeepSeek V4 Pro); all passed the same 33. We rerun within 45 days, or when a price or version changes, keeping each run.
Every model, dated
Each model's run: the day, the version that answered (as OpenRouter reported it), what it passed of our 50 prompts, and the day that run stops counting. Ranked by our published rule.
| Model | Ran on | Version that answered | Passed | Hard ones | Counts until |
|---|---|---|---|---|---|
| DeepSeek V4 Pro | October 8, 2026 | deepseek/deepseek-v4-pro-0813 | 49 of 50 | 20 of 20 | November 22, 2026 |
| Gemini 3.1 Pro | September 27, 2026 | google/gemini-3.1-pro-preview | 49 of 50 | 19 of 20 | November 11, 2026 |
| Claude Opus 5.5 | September 27, 2026 | anthropic/claude-opus-5.5 | 49 of 50 | 19 of 20 | November 11, 2026 |
| GPT-6 Astra | September 27, 2026 | openai/gpt-6-astra | 48 of 50 | 20 of 20 | November 11, 2026 |
| DeepSeek V4.1 Flash | October 8, 2026 | deepseek/deepseek-v4.1-flash | 48 of 50 | 19 of 20 | November 22, 2026 |
| GLM 5.3 | September 27, 2026 | z-ai/glm-5.3 | 48 of 50 | 19 of 20 | November 11, 2026 |
| GPT-6 Luna | September 27, 2026 | openai/gpt-6-luna | 47 of 50 | 20 of 20 | November 11, 2026 |
| Grok 4.7 | October 2, 2026 | x-ai/grok-4.7 | 47 of 50 | 19 of 20 | November 16, 2026 |
| Claude Sonnet 5.5 | September 28, 2026 | anthropic/claude-sonnet-5.5 | 47 of 50 | 19 of 20 | November 12, 2026 |
| Gemini 4 Argon | October 15, 2026 | google/gemini-4-argon | 47 of 50 | 19 of 20 | November 29, 2026 |
| Mistral Large 4 | October 9, 2026 | mistralai/mistral-large-4-0 | 47 of 50 | 17 of 20 | November 23, 2026 |
| GPT-6.1 Sol | September 29, 2026 | openai/gpt-6.1-sol | 46 of 50 | 19 of 20 | November 13, 2026 |
| Claude Sonnet 5 | September 27, 2026 | anthropic/claude-sonnet-5 | 46 of 50 | 19 of 20 | November 11, 2026 |
| Gemini 3.8 Flash | September 27, 2026 | google/gemini-3.8-flash | 46 of 50 | 18 of 20 | November 11, 2026 |
| Kimi K3 | September 27, 2026 | moonshotai/kimi-k3 | 46 of 50 | 18 of 20 | November 11, 2026 |
| Claude Haiku 5.5 | October 7, 2026 | anthropic/claude-haiku-5.5 | 45 of 50 | 19 of 20 | November 21, 2026 |
| GPT-6 Sol | September 27, 2026 | openai/gpt-6-sol | 45 of 50 | 19 of 20 | November 11, 2026 |
| Claude Fable 5.1 | September 27, 2026 | anthropic/claude-fable-5.1 | 45 of 50 | 17 of 20 | November 11, 2026 |
| Claude Haiku 4.5 | September 27, 2026 | anthropic/claude-haiku-4.5 | 43 of 50 | 15 of 20 | November 11, 2026 |
| GLM 5.3 Flash | September 27, 2026 | z-ai/glm-5.3-flash | 40 of 50 | 16 of 20 | November 11, 2026 |
Every prompt, every model
Each prompt with how many models passed it and which didn't: when a model changes, these are the rows that move first.
| Prompt | Job | Passed | Failed by |
|---|---|---|---|
| Turn a title into a URL slug | Coding, everyday | 20 of 20 | none |
| Parse a duration like “1h 30m” | Coding, everyday | 20 of 20 | none |
| Merge overlapping intervals | Coding, everyday | 20 of 20 | none |
| Evaluate an arithmetic expression, no eval | Coding, hard | 18 of 20 | Claude Haiku 4.5, Mistral Large 4 |
| Parse CSV with quoted fields | Coding, hard | 19 of 20 | Claude Haiku 4.5 |
| Announce a second bakery shop on LinkedIn | Writing, everyday | 19 of 20 | Claude Sonnet 5 |
| Rewrite corporate jargon in plain words | Writing, everyday | 13 of 20 | Claude Haiku 5.5, GPT-6.1 Sol, GPT-6 Sol, Gemini 3.8 Flash, DeepSeek V4.1 Flash, Grok 4.7, GLM 5.3 Flash |
| Decline a meeting and offer two times | Writing, everyday | 20 of 20 | none |
| A product announcement with five rules | Writing, hard | 14 of 20 | Claude Fable 5.1, Claude Haiku 4.5, Gemini 3.8 Flash, Kimi K3, GLM 5.3 Flash, Mistral Large 4 |
| Argue both sides of free buses | Writing, hard | 11 of 20 | Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5, Claude Haiku 5.5, Gemini 4 Argon, Gemini 3.1 Pro, Grok 4.7, GLM 5.3, GLM 5.3 Flash |
| A discount, then sales tax | Math, everyday | 20 of 20 | none |
| Pens at 3 for $4 | Math, everyday | 19 of 20 | GPT-6 Luna |
| Compound interest over three years | Math, everyday | 20 of 20 | none |
| Four-digit numbers whose digits sum to 9 | Math, hard | 20 of 20 | none |
| The highest of three dice is a 5 | Math, hard | 20 of 20 | none |
| An article in three bullets | Summarization, everyday | 12 of 20 | Claude Fable 5.1, Claude Sonnet 5, Claude Haiku 5.5, GPT-6 Sol, GPT-6 Luna, Kimi K3, GLM 5.3, GLM 5.3 Flash |
| An email thread in one sentence | Summarization, everyday | 14 of 20 | Claude Fable 5.1, Claude Sonnet 5.5, Claude Sonnet 5, Claude Haiku 5.5, Kimi K3, GLM 5.3 Flash |
| Decisions and action items from a meeting | Summarization, everyday | 20 of 20 | none |
| A quarterly memo for the CEO | Summarization, hard | 20 of 20 | none |
| A study with a negative result | Summarization, hard | 20 of 20 | none |
| The region with the most revenue | Data analysis, everyday | 20 of 20 | none |
| Average order value in August | Data analysis, everyday | 19 of 20 | Claude Haiku 4.5 |
| Revenue change from July to August | Data analysis, everyday | 20 of 20 | none |
| A median, filtered two ways | Data analysis, hard | 20 of 20 | none |
| Correlation between ad spend and sign-ups | Data analysis, hard | 16 of 20 | Claude Sonnet 5, Claude Haiku 4.5, Gemini 3.8 Flash, GLM 5.3 Flash |
| A late order | Customer support, everyday | 15 of 20 | GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, Gemini 4 Argon, GLM 5.3 Flash |
| A return inside the window | Customer support, everyday | 20 of 20 | none |
| A frustrated customer | Customer support, everyday | 8 of 20 | Claude Sonnet 5.5, Claude Haiku 5.5, Claude Haiku 4.5, GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna, Gemini 4 Argon, Gemini 3.8 Flash, DeepSeek V4 Pro, Grok 4.7, GLM 5.3 Flash |
| A refund request outside the window | Customer support, hard | 16 of 20 | GPT-6.1 Sol, Kimi K3, GLM 5.3 Flash, Mistral Large 4 |
| A message with a planted instruction | Customer support, hard | 17 of 20 | Claude Fable 5.1, Claude Haiku 4.5, DeepSeek V4.1 Flash |
| A delivery message into Spanish | Translation, everyday | 20 of 20 | none |
| A product description into French | Translation, everyday | 20 of 20 | none |
| A meeting note into German | Translation, everyday | 20 of 20 | none |
| Idioms into natural Japanese | Translation, hard | 19 of 20 | GPT-6 Sol |
| A lease clause into Brazilian Portuguese | Translation, hard | 20 of 20 | none |
| Customers in one country | SQL, everyday | 20 of 20 | none |
| Count orders by status | SQL, everyday | 20 of 20 | none |
| Revenue by category | SQL, everyday | 20 of 20 | none |
| Every customer, even those without orders | SQL, hard | 20 of 20 | none |
| Monthly revenue with a running total | SQL, hard | 20 of 20 | none |
| A fact from one section | RAG and answering from documents, everyday | 20 of 20 | none |
| Core hours and start times | RAG and answering from documents, everyday | 20 of 20 | none |
| Two sections in one answer | RAG and answering from documents, everyday | 20 of 20 | none |
| A later amendment changes the answer | RAG and answering from documents, hard | 20 of 20 | none |
| A question the handbook doesn't answer | RAG and answering from documents, hard | 20 of 20 | none |
| Pick the tool and work out the date | Agents and tool use, everyday | 20 of 20 | none |
| Convert a currency | Agents and tool use, everyday | 20 of 20 | none |
| Book a meeting from a sentence | Agents and tool use, everyday | 19 of 20 | GLM 5.3 Flash |
| Search, but don't book | Agents and tool use, hard | 20 of 20 | none |
| Two calls with a unit conversion | Agents and tool use, hard | 20 of 20 | none |
More AI data
- Messages per $20: every AI plan that publishes a count, and llmwise's
- AI price and limit changelog: every dated change, sourced
- Which AI plan gets the newest models? Plan by plan
- AI chat privacy scorecard: who trains on your chats, and for how long they keep them
- Price per task: what finishing an AI task costs, model by model
- The AI model leaderboard, job by job
- Subscription stack calculator: what your AI plans cost together
- AI data studies: prices, limits, access and privacy
Also from primary sources: OpenRouter's usage accounting docs (the cost OpenRouter reports for every request, which these figures add up). Anthropic's Claude Opus 5.5 page (the model that grades the rubric prompts). OpenAI's GPT-6 Astra docs (the model that grades Claude Opus 5.5's own replies). Read .
The quality tracker: method
Has a model got worse?
Not from these runs yet: each model has run the prompts once, so there's nothing earlier to hold them against. Each re-run will be kept and shown here beside this one, with the version that answered, so a change shows as a change.
How often are the prompts run again?
Within 45 days of the last run, and sooner when a model's price or version changes in our catalog: a run of a model at another price or version no longer counts, and the pages built on it say so.
What's tested?
The same prompts, sent the way llmwise sends a message, checked the same way for every model: tests that run the code, the final answer for math and data analysis, the query's result for SQL, the key facts for documents, the tool calls for agents, a grader model's published rubric for writing, summaries and support, and back-translation for translation.
Check a model on your own question
The tracker scores 50 fixed prompts. Your questions may rank the models differently: ask two of them the same thing in one llmwise chat.