AI data
Updated · By llmwise, AI-assisted.
The AI model leaderboard, job by job
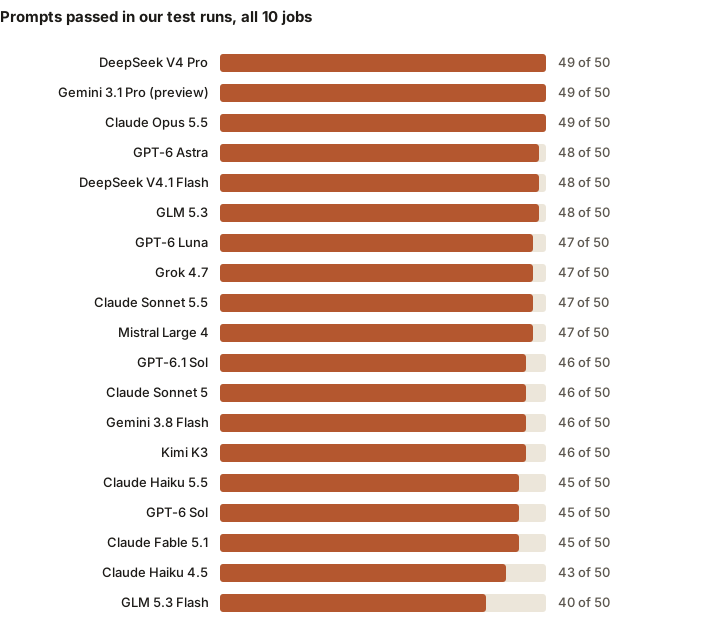
Each job's leaderboard from our test runs of September 27, 28, 29 and October 2, 7, 8, 9, 2026: all 19 models ranked on its five prompts by passes, then hard passes, then message size and cost. The top of the table runs from 3 models sharing first on writing to 19 sharing it on RAG and answering from documents.
Every job added up, in one order: the best AI model right now.
Coding: the leaderboard
Our picks and every reply: The best AI for coding.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GLM 5.3 Flash | =1 | 5 of 5 | 2 of 2 | $0.00025 | 8.0 s |
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.00029 | 4.9 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00045 | 4.0 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.0018 | 3.9 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.0015 | 3.5 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.0020 | 4.4 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.0240 | 79.6 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0246 | 46.9 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.0023 | 4.9 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0052 | 5.7 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0063 | 3.0 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0063 | 5.2 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0102 | 8.0 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0195 | 13.2 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0171 | 8.3 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0223 | 6.8 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0425 | 9.1 s |
| Mistral Large 4 | 18 | 4 of 5 | 1 of 2 | $0.0073 | 41.0 s |
| Claude Haiku 4.5 | 19 | 3 of 5 | 0 of 2 | $0.0027 | 3.4 s |
Writing: the leaderboard
Our picks and every reply: The best AI for writing.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.000099 | 2.1 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.0011 | 3.8 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0111 | 4.9 s |
| DeepSeek V4.1 Flash | =4 | 4 of 5 | 2 of 2 | $0.00045 | 1.6 s |
| GPT-6.1 Sol | =4 | 4 of 5 | 2 of 2 | $0.0011 | 3.2 s |
| GPT-6 Sol | =4 | 4 of 5 | 2 of 2 | $0.0023 | 3.1 s |
| Claude Sonnet 5 | =4 | 4 of 5 | 2 of 2 | $0.0034 | 4.2 s |
| GLM 5.3 | =8 | 4 of 5 | 1 of 2 | $0.00057 | 1.7 s |
| Claude Haiku 4.5 | =8 | 4 of 5 | 1 of 2 | $0.0011 | 2.4 s |
| Mistral Large 4 | =8 | 4 of 5 | 1 of 2 | $0.0024 | 19.7 s |
| Claude Sonnet 5.5 | =8 | 4 of 5 | 1 of 2 | $0.0034 | 2.8 s |
| Kimi K3 | =8 | 4 of 5 | 1 of 2 | $0.0038 | 2.9 s |
| Gemini 3.1 Pro | =8 | 4 of 5 | 1 of 2 | $0.0092 | 8.6 s |
| Claude Opus 5.5 | =8 | 4 of 5 | 1 of 2 | $0.0185 | 9.7 s |
| Claude Haiku 5.5 | =15 | 3 of 5 | 1 of 2 | $0.00016 | 2.2 s |
| Gemini 3.8 Flash | =15 | 3 of 5 | 1 of 2 | $0.0013 | 4.7 s |
| Grok 4.7 | =15 | 3 of 5 | 1 of 2 | $0.0058 | 9.4 s |
| Claude Fable 5.1 | 18 | 3 of 5 | 0 of 2 | $0.0172 | 6.7 s |
| GLM 5.3 Flash | 19 | 2 of 5 | 0 of 2 | $0.00032 | 13.9 s |
Math: the leaderboard
Our picks and every reply: The best AI for math.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00015 | 1.7 s |
| GLM 5.3 Flash | =1 | 5 of 5 | 2 of 2 | $0.00015 | 5.1 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00025 | 1.1 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00035 | 1.1 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.00088 | 2.9 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.0014 | 3.8 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.0015 | 2.4 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0018 | 10.2 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0072 | 11.6 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.00086 | 2.0 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0018 | 2.2 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0025 | 1.7 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0033 | 4.1 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0037 | 4.9 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0100 | 7.5 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0060 | 4.1 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0085 | 2.7 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0116 | 4.6 s |
| GPT-6 Luna | 19 | 4 of 5 | 2 of 2 | $0.000098 | 2.4 s |
Summarization: the leaderboard
Our picks and every reply: The best AI for summarization.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00020 | 0.9 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.00075 | 3.7 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.00091 | 2.6 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.0010 | 1.9 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0028 | 3.5 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0043 | 27.3 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.0010 | 2.0 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0088 | 8.3 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0095 | 4.7 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0109 | 3.0 s |
| GPT-6 Luna | =11 | 4 of 5 | 2 of 2 | $0.000094 | 1.4 s |
| GLM 5.3 | =11 | 4 of 5 | 2 of 2 | $0.00054 | 1.4 s |
| GPT-6 Sol | =11 | 4 of 5 | 2 of 2 | $0.0022 | 2.4 s |
| Claude Sonnet 5.5 | =11 | 4 of 5 | 2 of 2 | $0.0034 | 2.0 s |
| GLM 5.3 Flash | =15 | 3 of 5 | 2 of 2 | $0.00011 | 4.4 s |
| Claude Haiku 5.5 | =15 | 3 of 5 | 2 of 2 | $0.00032 | 3.0 s |
| Claude Sonnet 5 | =15 | 3 of 5 | 2 of 2 | $0.0028 | 2.7 s |
| Kimi K3 | =15 | 3 of 5 | 2 of 2 | $0.0034 | 6.3 s |
| Claude Fable 5.1 | =15 | 3 of 5 | 2 of 2 | $0.0161 | 4.6 s |
Data analysis: the leaderboard
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.00018 | 3.4 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00036 | 3.2 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00085 | 1.8 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.0019 | 2.4 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.0029 | 4.1 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0037 | 16.4 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0111 | 16.1 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.0016 | 3.5 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0034 | 3.5 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0047 | 2.4 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0068 | 7.0 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0155 | 9.9 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0131 | 5.9 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0154 | 4.0 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0283 | 6.7 s |
| GLM 5.3 Flash | =16 | 4 of 5 | 1 of 2 | $0.00038 | 11.2 s |
| Gemini 3.8 Flash | =16 | 4 of 5 | 1 of 2 | $0.0028 | 5.4 s |
| Claude Sonnet 5 | =16 | 4 of 5 | 1 of 2 | $0.0069 | 6.9 s |
| Claude Haiku 4.5 | 19 | 3 of 5 | 1 of 2 | $0.0025 | 3.2 s |
Customer support: the leaderboard
Our picks and every reply: The best AI for customer support.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00047 | 2.6 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0036 | 3.7 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0106 | 8.7 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0108 | 6.5 s |
| GPT-6 Luna | =5 | 4 of 5 | 2 of 2 | $0.000086 | 1.4 s |
| Claude Haiku 5.5 | =5 | 4 of 5 | 2 of 2 | $0.00023 | 2.4 s |
| DeepSeek V4 Pro | =5 | 4 of 5 | 2 of 2 | $0.0015 | 4.8 s |
| Gemini 3.8 Flash | =5 | 4 of 5 | 2 of 2 | $0.0016 | 4.6 s |
| Grok 4.7 | =5 | 4 of 5 | 2 of 2 | $0.0061 | 9.8 s |
| Claude Sonnet 5.5 | =5 | 4 of 5 | 2 of 2 | $0.0046 | 3.1 s |
| DeepSeek V4.1 Flash | =11 | 4 of 5 | 1 of 2 | $0.00046 | 1.4 s |
| Mistral Large 4 | =11 | 4 of 5 | 1 of 2 | $0.0015 | 7.2 s |
| Kimi K3 | =11 | 4 of 5 | 1 of 2 | $0.0046 | 5.3 s |
| Claude Fable 5.1 | =11 | 4 of 5 | 1 of 2 | $0.0221 | 5.9 s |
| GPT-6 Sol | =15 | 3 of 5 | 2 of 2 | $0.0029 | 3.6 s |
| GPT-6 Astra | =15 | 3 of 5 | 2 of 2 | $0.0116 | 3.6 s |
| Claude Haiku 4.5 | 17 | 3 of 5 | 1 of 2 | $0.0015 | 2.6 s |
| GLM 5.3 Flash | =18 | 2 of 5 | 1 of 2 | $0.00019 | 5.4 s |
| GPT-6.1 Sol | =18 | 2 of 5 | 1 of 2 | $0.0012 | 3.0 s |
Translation: the leaderboard
Our picks and every reply: The best AI for translation.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.000093 | 1.7 s |
| GLM 5.3 Flash | =1 | 5 of 5 | 2 of 2 | $0.000099 | 3.7 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00018 | 1.7 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00058 | 1.4 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00070 | 1.6 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.00075 | 3.1 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.0015 | 2.3 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.0020 | 6.7 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0031 | 16.8 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0082 | 13.8 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.0013 | 3.2 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0030 | 3.2 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0036 | 5.3 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0042 | 2.6 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0140 | 10.4 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0108 | 5.9 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0126 | 4.2 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0175 | 5.6 s |
| GPT-6 Sol | 19 | 4 of 5 | 1 of 2 | $0.0028 | 3.5 s |
SQL: the leaderboard
Our picks and every reply: The best AI for SQL.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.000089 | 1.5 s |
| GLM 5.3 Flash | =1 | 5 of 5 | 2 of 2 | $0.00013 | 1.7 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00020 | 0.7 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00022 | 1.6 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00032 | 1.5 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.00074 | 3.6 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.00099 | 1.4 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.0020 | 7.4 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0022 | 9.3 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0048 | 6.1 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.00099 | 2.0 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0021 | 1.9 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0024 | 1.9 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0028 | 2.5 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0038 | 1.9 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0077 | 7.3 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0092 | 4.4 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0098 | 2.8 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0185 | 4.5 s |
RAG and answering from documents: the leaderboard
Our picks and every reply: The best AI for RAG and answering from documents.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.000077 | 1.3 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00014 | 1.2 s |
| GLM 5.3 Flash | =1 | 5 of 5 | 2 of 2 | $0.00015 | 2.3 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00017 | 0.5 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00050 | 0.8 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.00060 | 3.1 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.00066 | 3.2 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.0010 | 1.3 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0014 | 11.1 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0029 | 2.4 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.00079 | 1.5 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0015 | 3.2 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0016 | 1.3 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0022 | 1.9 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0028 | 1.3 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0058 | 6.2 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0073 | 3.8 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0079 | 1.8 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0145 | 4.9 s |
Agents and tool use: the leaderboard
Our picks and every reply: The best AI for agents and tool use.
| Model | Place | Passed | Hard ones | Per reply | Time |
|---|---|---|---|---|---|
| GPT-6 Luna | =1 | 5 of 5 | 2 of 2 | $0.000081 | 1.7 s |
| Claude Haiku 5.5 | =1 | 5 of 5 | 2 of 2 | $0.00014 | 1.6 s |
| DeepSeek V4.1 Flash | =1 | 5 of 5 | 2 of 2 | $0.00020 | 0.5 s |
| GLM 5.3 | =1 | 5 of 5 | 2 of 2 | $0.00044 | 1.0 s |
| DeepSeek V4 Pro | =1 | 5 of 5 | 2 of 2 | $0.00066 | 2.0 s |
| Gemini 3.8 Flash | =1 | 5 of 5 | 2 of 2 | $0.00087 | 4.6 s |
| Claude Haiku 4.5 | =1 | 5 of 5 | 2 of 2 | $0.00095 | 1.1 s |
| Mistral Large 4 | =1 | 5 of 5 | 2 of 2 | $0.0013 | 5.6 s |
| Grok 4.7 | =1 | 5 of 5 | 2 of 2 | $0.0039 | 6.1 s |
| GPT-6.1 Sol | =1 | 5 of 5 | 2 of 2 | $0.00073 | 1.6 s |
| GPT-6 Sol | =1 | 5 of 5 | 2 of 2 | $0.0016 | 1.9 s |
| Claude Sonnet 5 | =1 | 5 of 5 | 2 of 2 | $0.0024 | 3.0 s |
| Claude Sonnet 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0026 | 1.8 s |
| Kimi K3 | =1 | 5 of 5 | 2 of 2 | $0.0027 | 2.4 s |
| Gemini 3.1 Pro | =1 | 5 of 5 | 2 of 2 | $0.0057 | 5.7 s |
| Claude Opus 5.5 | =1 | 5 of 5 | 2 of 2 | $0.0050 | 3.8 s |
| GPT-6 Astra | =1 | 5 of 5 | 2 of 2 | $0.0068 | 2.0 s |
| Claude Fable 5.1 | =1 | 5 of 5 | 2 of 2 | $0.0119 | 3.8 s |
| GLM 5.3 Flash | 19 | 4 of 5 | 2 of 2 | $0.00013 | 3.7 s |
More AI data
- Messages per $20: every AI plan that publishes a count, and llmwise's
- AI price and limit changelog: every dated change, sourced
- Which AI plan gets the newest models? Plan by plan
- AI chat privacy scorecard: who trains on your chats, and for how long they keep them
- Price per task: what finishing an AI task costs, model by model
- AI model quality tracker: the same prompts, every model, dated
- AI data studies: prices, limits, access and privacy
Also from primary sources: OpenRouter's usage accounting docs (the cost OpenRouter reports for every request, which these figures add up). Anthropic's Claude Opus 5.5 page (the model that grades the rubric prompts). OpenAI's GPT-6 Astra docs (the model that grades Claude Opus 5.5's own replies). Read .
The leaderboard: how it's ranked
Where's the overall ranking?
The overall ranking, every job added up, is on “The best AI model right now”. This page is each job on its own, where the order changes: a model that leads overall can sit mid-table on one job.
How is each job ranked?
By how many of the job's prompts each model passed, then how many of the hard ones, then by the smaller message (the everyday models first), then the lower cost per reply. A place shared on passes and hard passes is marked “=”.
The leaders, on your own work
A ranking says how models did on five prompts per job. Try the top two on your work: switch models mid-chat, and the next one sees the whole conversation.