Comparison · Data analysis
Claude vs ChatGPT for data analysis
On llmwise Pro, Claude Sonnet 5.5 gets up to 125 messages a month and GPT-6.1 Sol up to 125 messages a month. ChatGPT is OpenAI's own app for its GPT models; llmwise has GPT models in its own chat, not ChatGPT itself. We ran the same 5 data analysis prompts on all 6 Claude models and all 4 GPT models and published every reply: the results, then Claude Haiku 5.5 against GPT-6 Luna prompt by prompt, then how Claude and GPT compare on price per message, context and files.
Based on 50 of our test runs on , through OpenRouter with the app's own prompt and settings. Updated .
Short answer
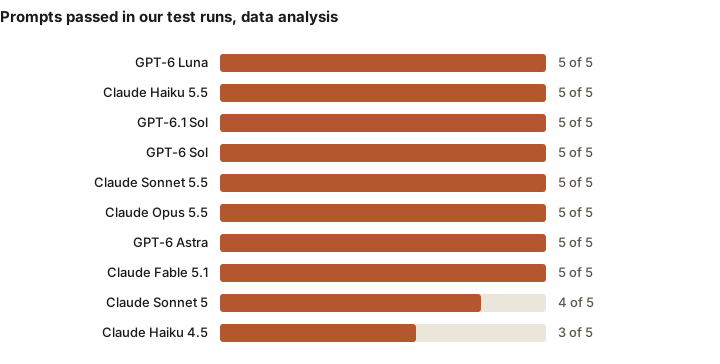
In our data analysis test runs on October 7, 2026, Claude's 6 models passed 27 of 30; Claude Fable 5.1, Claude Opus 5.5 and 2 more each passed 5 of 5. GPT's 4 models passed 20 of 20; GPT-6 Astra, GPT-6.1 Sol and 2 more each passed 5 of 5. Claude Haiku 5.5 and GPT-6 Luna each passed 5 of the 5 prompts, so these data analysis prompts don't split Claude and GPT; the replies on this page show how they differ.
Claude and GPT on our data analysis test runs
Every Claude and GPT model in llmwise on our 5 data analysis prompts: how many replies passed, what each counted as on Pro, and what it cost to run.
| Model | Passed | Hard ones | Messages used on Pro | Cost per reply | Time per reply |
|---|---|---|---|---|---|
| Claude Fable 5.1Anthropic | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0283 | 6.7 s |
| Claude Opus 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 62 a month on Pro | $0.0131 | 5.9 s |
| Claude Sonnet 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0047 | 2.4 s |
| Claude Sonnet 5Anthropic | 4 of 5 | 1 of 2 | 1 each, of 125 a month on Pro | $0.0069 | 6.9 s |
| Claude Haiku 4.5Anthropic | 3 of 5 | 1 of 2 | 1 each, of 250 a month on Pro | $0.0025 | 3.2 s |
| Claude Haiku 5.5Anthropic | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0004 | 3.2 s |
| GPT-6 AstraOpenAI | 5 of 5 | 2 of 2 | 1 each, of 31 a month on Pro | $0.0154 | 4.0 s |
| GPT-6.1 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0016 | 3.5 s |
| GPT-6 SolOpenAI | 5 of 5 | 2 of 2 | 1 each, of 125 a month on Pro | $0.0034 | 3.5 s |
| GPT-6 LunaOpenAI | 5 of 5 | 2 of 2 | 1 each, of 60 a day on Pro | $0.0002 | 3.4 s |
Every limit is published. Paid plans also have a monthly fair-use limit on AI cost: Plus $3.75, Pro $7.50, Max $20, Ultra $42, Studio $85. Using every message on your plan at typical sizes stays under it; very large messages and heavy research use it faster. Every limit, explained.
Claude vs GPT, prompt by prompt
Each data analysis prompt with Claude Haiku 5.5 and GPT-6 Luna side by side, as they replied: for each side, the model that passed the most data analysis prompts (then the most hard ones, then the cheaper).
Data analysis: Claude Haiku 5.5 passed 5 of 5 and GPT-6 Luna 5 of 5. GPT-6 Luna answered 1.3× sooner at the median, 3.3 s against 2.5 s. GPT-6 Luna cost 2.0× less, $0.0018 against $0.0009 for the 5 replies. Claude Haiku 5.5's replies ran 157% longer, in tokens of reply, thinking not counted.
1. The region with the most revenue
Everyday. Claude: 6 of 6 models passed, Claude Haiku 5.5 the cheapest at $0.0003 · GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001. The prompt in full.
Claude Haiku 5.5 and GPT-6 Luna both passed this one. GPT-6 Luna answered sooner (2.5 s to 3.4 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0003); Claude Haiku 5.5 wrote 105 tokens of reply, GPT-6 Luna 70.
Claude Haiku 5.5
Passed: Final answer North, 1085: right.
Revenue = quantity × price, summed by region:

- **West:** 90 + 310 + 240 + 225 = **865**
- **East:** 120 + 135 + 310 + 360 = **925**
- **North:** 180 + 240 + 620 + 45 = **1085**

Final answer: North, 1085
816 tokens in, 336 out (231 of them reasoning) · 3.4 s · $0.0003 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
GPT-6 Luna
Passed: Final answer North — 1,085.00: right.
West: $90 + $310 + $240 + $225 = $865
East: $120 + $135 + $310 + $360 = $925
North: $180 + $240 + $620 + $45 = $1,085

Final answer: North — $1,085.00
640 tokens in, 135 out (65 of them reasoning) · 2.5 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
2. Average order value in August
Everyday. Claude: 5 of 6 models passed, Claude Haiku 5.5 the cheapest at $0.0002 · GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001. The prompt in full.
Claude Haiku 5.5 and GPT-6 Luna both passed this one. Claude Haiku 5.5 answered sooner (1.3 s to 2.6 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0002); Claude Haiku 5.5 wrote 208 tokens of reply, GPT-6 Luna 64.
Claude Haiku 5.5
Passed: Final answer 300.00: right.
August orders (1007–1012):

- 1007: 2 × 120.00 = 240.00
- 1008: 1 × 310.00 = 310.00
- 1009: 2 × 310.00 = 620.00
- 1010: 5 × 45.00 = 225.00
- 1011: 3 × 120.00 = 360.00
- 1012: 1 × 45.00 = 45.00

Total revenue: 240 + 310 + 620 + 225 + 360 + 45 = 1,800.00

Number of orders: 6

Average: 1,800.00 / 6 = 300.00

Final answer: 300.00
824 tokens in, 208 out · 1.3 s · $0.0002 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
GPT-6 Luna
Passed: Final answer 300.00: right.
August revenue: $240 + $310 + $620 + $225 + $360 + $45 = $1,800.
There were 6 orders, so the average is $1,800 ÷ 6 = $300.00.

Final answer: $300.00
647 tokens in, 131 out (67 of them reasoning) · 2.6 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
3. Revenue change from July to August
Everyday. Claude: 6 of 6 models passed, Claude Haiku 5.5 the cheapest at $0.0004 · GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001. The prompt in full.
Claude Haiku 5.5 and GPT-6 Luna both passed this one. GPT-6 Luna answered sooner (2.5 s to 3.3 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0004); Claude Haiku 5.5 wrote 298 tokens of reply, GPT-6 Luna 66.
Claude Haiku 5.5
Passed: Final answer 67.4%: right.
**July 2026 revenue:**
- 1001: 2 × 45 = 90
- 1002: 1 × 120 = 120
- 1003: 1 × 310 = 310
- 1004: 4 × 45 = 180
- 1005: 3 × 45 = 135
- 1006: 2 × 120 = 240
- Total: **1,075**

**August 2026 revenue:**
- 1007: 2 × 120 = 240
- 1008: 1 × 310 = 310
- 1009: 2 × 310 = 620
- 1010: 5 × 45 = 225
- 1011: 3 × 120 = 360
- 1012: 1 × 45 = 45
- Total: **1,800**

**Change:** (1,800 − 1,075) / 1,075 = 725 / 1,075 ≈ 0.6744, or 67.4%.

Final answer: 67.4%
832 tokens in, 575 out (277 of them reasoning) · 3.3 s · $0.0004 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
GPT-6 Luna
Passed: Final answer 67.4% increase: right.
July revenue: $1,075.00. August revenue: $1,800.00.

Percentage change = (($1,800 − $1,075) ÷ $1,075) × 100 = 67.4% increase.

Final answer: 67.4% increase
652 tokens in, 135 out (69 of them reasoning) · 2.5 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
4. A median, filtered two ways
Hard. Claude: 6 of 6 models passed, Claude Haiku 5.5 the cheapest at $0.0002 · GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0001. The prompt in full.
Claude Haiku 5.5 and GPT-6 Luna both passed this one. They took about as long (Claude Haiku 5.5 2.6 s, GPT-6 Luna 2.5 s), and GPT-6 Luna's reply cost less ($0.0001 to $0.0002); Claude Haiku 5.5 wrote 126 tokens of reply, GPT-6 Luna 75.
Claude Haiku 5.5
Passed: Final answer 6.25: right.
Billing tickets with high priority:

- T1: 5.5
- T4: 2
- T6: 9
- T9: 7
- T10: 26
- T12: 4

Sorted: 2, 4, 5.5, 7, 9, 26

With six values, the median is the average of the middle two: (5.5 + 7) / 2 = 6.25

Final answer: 6.25
692 tokens in, 240 out (114 of them reasoning) · 2.6 s · $0.0002 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
GPT-6 Luna
Passed: Final answer 6.25 hours: right.
Billing high-priority resolution times, sorted: 2, 4, 5.5, 7, 9, 26. With six values, the median is the average of the middle two: (5.5 + 7) / 2 = 6.25 hours.

Final answer: 6.25 hours
512 tokens in, 128 out (53 of them reasoning) · 2.5 s · $0.0001 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
5. Correlation between ad spend and sign-ups
Hard. Claude: 4 of 6 models passed, Claude Haiku 5.5 the cheapest at $0.0007 · GPT: 4 of 4 models passed, GPT-6 Luna the cheapest at $0.0004. The prompt in full.
Claude Haiku 5.5 and GPT-6 Luna both passed this one. Claude Haiku 5.5 answered sooner (5.7 s to 6.7 s), and GPT-6 Luna's reply cost less ($0.0004 to $0.0007); Claude Haiku 5.5 wrote 223 tokens of reply, GPT-6 Luna 99.
Claude Haiku 5.5
Passed: Final answer 0.97: right.
**Working:**

- n = 8
- Mean ad_spend = 6150 / 8 = 768.75
- Mean signups = 434 / 8 = 54.25
- Sum of cross-deviations (Σ(x−x̄)(y−ȳ)) = 23,912.5
- Sum of squared x-deviations (Σ(x−x̄)²) = 624,687.5
- Sum of squared y-deviations (Σ(y−ȳ)²) = 971.5

r = 23,912.5 / √(624,687.5 × 971.5) ≈ 23,912.5 / 24,635.9 ≈ 0.971

Final answer: 0.97
608 tokens in, 1,298 out (1,075 of them reasoning) · 5.7 s · $0.0007 · 1 message on Pro · answered by anthropic/claude-haiku-5.5 via Anthropic ·
GPT-6 Luna
Passed: Final answer 0.97: right.
Using \(r=\frac{\sum (x-\bar{x})(y-\bar{y})}{\sqrt{\sum(x-\bar{x})^2\sum(y-\bar{y})^2}}\), the centered sums are \(23{,}912.5\), \(624{,}687.5\), and \(971.5\). Thus \(r \approx 0.9707\).

Final answer: 0.97
451 tokens in, 651 out (552 of them reasoning) · 6.7 s · $0.0004 · 1 message on Pro · answered by openai/gpt-6-luna via OpenAI ·
Each Claude model against each GPT model
Every Claude model against every GPT model on the same 5 data analysis prompts: passes, the median wait and what the replies cost. A lead under 10% counts as close.
Claude Fable 5.1 vs GPT-6 Astra: 5 of 5 each; GPT-6 Astra answered 1.5× sooner at the median and cost 1.8× less. Claude Fable 5.1 vs GPT-6 Astra, on every job.
Claude Fable 5.1 vs GPT-6.1 Sol: 5 of 5 each; GPT-6.1 Sol answered 1.6× sooner at the median and cost 17.8× less.
Claude Fable 5.1 vs GPT-6 Sol: 5 of 5 each; GPT-6 Sol answered 1.7× sooner at the median and cost 8.4× less.
Claude Fable 5.1 vs GPT-6 Luna: 5 of 5 each; GPT-6 Luna answered 2.0× sooner at the median and cost 160.7× less.
Claude Opus 5.5 vs GPT-6 Astra: 5 of 5 each; GPT-6 Astra answered 1.4× sooner at the median and Claude Opus 5.5 cost 1.2× less. Claude Opus 5.5 vs GPT-6 Astra, on every job.
Claude Opus 5.5 vs GPT-6.1 Sol: 5 of 5 each; GPT-6.1 Sol answered 1.5× sooner at the median and cost 8.2× less.
Claude Opus 5.5 vs GPT-6 Sol: 5 of 5 each; GPT-6 Sol answered 1.6× sooner at the median and cost 3.9× less. Claude Opus 5.5 vs GPT-6 Sol, on every job.
Claude Opus 5.5 vs GPT-6 Luna: 5 of 5 each; GPT-6 Luna answered 1.8× sooner at the median and cost 74.3× less.
Claude Sonnet 5.5 vs GPT-6 Astra: 5 of 5 each; Claude Sonnet 5.5 answered 1.4× sooner at the median and cost 3.3× less.
Claude Sonnet 5.5 vs GPT-6.1 Sol: 5 of 5 each; Claude Sonnet 5.5 answered 1.3× sooner at the median and GPT-6.1 Sol cost 3.0× less. GPT-6.1 Sol vs Claude Sonnet 5.5, on every job.
Claude Sonnet 5.5 vs GPT-6 Sol: 5 of 5 each; Claude Sonnet 5.5 answered 1.2× sooner at the median and GPT-6 Sol cost 1.4× less. Claude Sonnet 5.5 vs GPT-6 Sol, on every job.
Claude Sonnet 5.5 vs GPT-6 Luna: 5 of 5 each; they took about as long and GPT-6 Luna cost 26.7× less.
Claude Sonnet 5 vs GPT-6 Astra: Claude Sonnet 5 4 of 5, GPT-6 Astra 5; GPT-6 Astra answered 1.6× sooner at the median and Claude Sonnet 5 cost 2.2× less.
Claude Sonnet 5 vs GPT-6.1 Sol: Claude Sonnet 5 4 of 5, GPT-6.1 Sol 5; GPT-6.1 Sol answered 1.8× sooner at the median and cost 4.3× less.
Claude Sonnet 5 vs GPT-6 Sol: Claude Sonnet 5 4 of 5, GPT-6 Sol 5; GPT-6 Sol answered 1.9× sooner at the median and cost 2.0× less. Claude Sonnet 5 vs GPT-6 Sol, on every job.
Claude Sonnet 5 vs GPT-6 Luna: Claude Sonnet 5 4 of 5, GPT-6 Luna 5; GPT-6 Luna answered 2.1× sooner at the median and cost 39.1× less.
Claude Haiku 4.5 vs GPT-6 Astra: Claude Haiku 4.5 3 of 5, GPT-6 Astra 5; Claude Haiku 4.5 answered 1.2× sooner at the median and cost 6.2× less.
Claude Haiku 4.5 vs GPT-6.1 Sol: Claude Haiku 4.5 3 of 5, GPT-6.1 Sol 5; they took about as long and GPT-6.1 Sol cost 1.6× less.
Claude Haiku 4.5 vs GPT-6 Sol: Claude Haiku 4.5 3 of 5, GPT-6 Sol 5; they took about as long and Claude Haiku 4.5 cost 1.4× less. Claude Haiku 4.5 vs GPT-6 Sol, on every job.
Claude Haiku 4.5 vs GPT-6 Luna: Claude Haiku 4.5 3 of 5, GPT-6 Luna 5; they took about as long and GPT-6 Luna cost 14.2× less. Claude Haiku 4.5 vs GPT-6 Luna, on every job.
Claude Haiku 5.5 vs GPT-6 Astra: 5 of 5 each; they took about as long and Claude Haiku 5.5 cost 43.1× less.
Claude Haiku 5.5 vs GPT-6.1 Sol: 5 of 5 each; they took about as long and Claude Haiku 5.5 cost 4.4× less.
Claude Haiku 5.5 vs GPT-6 Sol: 5 of 5 each; GPT-6 Sol answered 1.2× sooner at the median and Claude Haiku 5.5 cost 9.4× less.
Claude Haiku 5.5 vs GPT-6 Luna: 5 of 5 each; GPT-6 Luna answered 1.3× sooner at the median and cost 2.0× less. Claude Haiku 5.5 vs GPT-6 Luna, on every job.
How the data analysis replies are scored
Every Claude and GPT reply above was checked the same way as every other model's, by the rules published with the prompts: how the data analysis prompts are scored, and each one in full.
The differences at a glance
What follows from each model's facts in our catalog.
The lineups
Claude: 6 models, Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5, Claude Sonnet 5, Claude Haiku 4.5, and Claude Haiku 5.5. GPT: 4 models, GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, and GPT-6 Luna.
Price per message
The least expensive Claude model is Claude Haiku 5.5 (60 messages a day on Pro); the least expensive GPT model is GPT-6 Luna (60 messages a day on Pro).
Context window
Claude goes up to 1M tokens (Claude Fable 5.1); GPT up to 1.05M tokens (GPT-6 Astra).
Images and PDFs
Every model here reads images. Every model here takes a PDF as a whole file.
On the Free plan
Free's one-time trial of 5 messages covers Claude Haiku 5.5. Paid plans have them, with messages every month: Claude Fable 5.1 and GPT-6 Astra from Pro up.
Every Claude and GPT model's context window, files and API price: Claude vs ChatGPT.
Where your messages go
In llmwise, a message to Claude or GPT goes to the model's maker, or through OpenRouter when llmwise can't reach the maker directly. The Privacy Policy has the details.
Questions
Which is better, Claude or ChatGPT for data analysis?
In our data analysis test runs on October 7, 2026, Claude's 6 models passed 27 of 30; Claude Fable 5.1, Claude Opus 5.5 and 2 more each passed 5 of 5. GPT's 4 models passed 20 of 20; GPT-6 Astra, GPT-6.1 Sol and 2 more each passed 5 of 5. Claude Haiku 5.5 and GPT-6 Luna each passed 5 of the 5 prompts, so these data analysis prompts don't split Claude and GPT; the replies on this page show how they differ.
Is Claude or GPT cheaper?
In llmwise, the least expensive Claude model is Claude Haiku 5.5 (60 messages a day on Pro), and the least expensive GPT model is GPT-6 Luna (60 messages a day on Pro). At API list prices (October 2026), a typical message of 4,000 tokens in and 700 out costs $0.0008 on Claude Haiku 5.5 and $0.0008 on GPT-6 Luna.
Can I use Claude and GPT in the same chat?
Yes. Ask Claude Haiku 5.5 a question, then switch the picker to GPT-6 Luna and ask again: GPT-6 Luna sees the whole conversation, Claude Haiku 5.5's answer included.
Claude, GPT, Gemini, DeepSeek, Grok, Kimi, GLM, and Mistral, in one chat.
See what a message costs before you send it. Free is 5 messages to try; sign in with an email link, no password or card.